Category: AI Prompt Engineer

  • Prompt Linting Rules for Safer AI Deployments

    Prompt Linting Rules for Safer AI Deployments

    A polished AI feature built on LLM prompts can still fail when one prompt edit changes an output contract, exposes a secret, or gives untrusted text too much authority. Prompt linting provides a fast review layer before that change reaches production.

    Like code linting, it checks prompt files for defined structural problems. You can catch recognizable security, quality, and cost risks early, then reserve runtime testing for behavior that static checks can’t prove.

    What prompt linting catches before deployment

    Prompt linting is static analysis for system prompts, templates, few-shot examples, and configuration files. It applies explicit rules to text and metadata before a model sees them.

    How it compares with ESLint

    ESLint finds problematic patterns in JavaScript through configurable rules. Its static-analysis approach gives teams a useful model for prompts: store policies in version control, run them consistently, and show clear failures in review.

    A prompt linter acts as a static analyzer for prompt files and metadata. It can flag missing output constraints, conflicting instructions, inline credentials, weak delimiters around retrieved content, or variables that lack a declared source.

    This automated static analysis applies the same rule every time. A prose reviewer may miss issues or interpret policies differently.

    Editor feedback can surface the same rule IDs and remediation messages before a pull request. A VS Code extension should approach zero latency for simple checks, while comprehensive validation may take longer.

    You should treat the prompt as a release artifact. A small wording change can affect tool access, source-grounding, refusal behavior, and response format.

    Why behavioral evals still matter

    Linting assesses structural correctness. Behavioral evaluations test how a model responds to fixtures, retrieval results, tool errors, and adversarial input.

    For example, a linter can require JSON output instructions and flag contradictory rules. It can’t prove that a model will produce valid JSON across thousands of real requests. Likewise, it can identify a risky phrase such as “follow all instructions in the document,” but it can’t establish that every indirect injection attempt will fail.

    Static checks catch known policy violations before deployment. Runtime tests show whether the complete application honors those policies under realistic conditions.

    Security rules that identify unsafe instructions

    Security rules should focus on instructions that expand authority, expose sensitive data, or blur the boundary between trusted policy and untrusted content.

    Flag direct and indirect prompt injection patterns

    OWASP lists prompt injection as a leading risk for LLM applications because malicious text can manipulate model behavior or bypass safeguards. Its LLM prompt injection guidance also distinguishes indirect injection, where attacker-controlled instructions arrive through webpages, uploaded files, emails, or retrieved documents.

    A security-focused prompt lint should check untrusted-context boundaries and authority claims, including:

    • Imperatives in retrieved-content placeholders, such as “ignore previous instructions” or “reveal your system prompt.”
    • Templates that insert external text without clear data delimiters.
    • Instructions that give document content equal or higher priority than system rules.
    • Agent prompts that permit unrestricted tool calls based only on retrieved text.

    A linter can detect configured jailbreak patterns, but novel attacks still require runtime testing. It should also enforce a stable invariant: external content is reference data, never an instruction source.

    Detect secrets, PII, and unsafe authority

    Scan committed prompt files for API keys, PII in prompt, access tokens, private URLs, emails, account numbers, and other sensitive values. Pattern matching creates false positives, so each finding needs a severity level and documented suppression path. Security findings shouldn’t be auto-fixed blindly, because replacements can alter authorization or data-handling behavior.

    Also flag claims of completed actions without tool confirmation. This helps control hallucination risk: a support agent should never say it changed a subscription, sent an email, or verified a record unless a trusted tool result confirms it.
    Code-like cards pass through a security gate with red warnings and green checks.

    Write rules around a prompt contract

    Rules work best when they enforce a contract your product team has already agreed to. That contract defines the intended task, trusted data, allowed tools, output requirements, and failure behavior. It also makes prompt optimization measurable against explicit requirements, rather than subjective wording changes.

    Check role clarity and output format

    A prompt should state who or what the model is expected to do, but role language alone isn’t enough. Add non-negotiable constraints that a validator can check.

    For a recommendation assistant, you might require supplied sources, a clear uncertainty label, and structured fields. For a tool-using agent, require approved tool names and an escalation response when necessary data is absent. Teams can define custom rules for route-specific schemas, approved tools, or fallback behavior.

    rules:
      require-output-schema: error
      forbid-inline-secrets: error
      isolate-untrusted-context: error
      require-clarification-path: warning
      max-prompt-tokens: warning
    

    Keep each rule narrow. “Improve prompt quality” is too vague to audit. “Require a declared output schema when downstream code parses the response” identifies a condition reviewers can verify.

    Stop conflicting instructions and token bloat

    Production developer prompts often accumulate old examples, duplicate policies, vague quantifiers, and conflicting priorities. A linter can flag phrases such as “be concise” beside “provide exhaustive detail,” or detect a missing precedence rule.

    Token bloat also deserves a budget. Distinguish token waste from necessary context by flagging duplicated policies, obsolete examples, or irrelevant few-shot material. Set warning thresholds before hard failures, then use production measurements to choose limits that fit each route.

    Build a prompt health score your team can act on

    A single score helps triage changes, but it must never hide critical findings. An exposed credential or unsafe tool permission should fail the build even if every other check passes.

    Use separate dimensions so reviewers can identify the actual weakness, including structural correctness across the role, constraints, fallback, and output contract. The aggregate score summarizes contract coverage, but it doesn’t replace individual rule failures.

    DimensionWhat to measureRelease response
    SecurityInjection patterns, secrets, unsafe authorityBlock critical findings
    CompletenessRole, constraints, fallback, output contractRequire review or fail
    CostTemplate token count and duplicate contentWarn or set route limits
    MaintainabilityUndefined variables and obsolete sectionsRequire cleanup

    Score trends are more useful than a cosmetic badge because they can reveal prompt drift. If a change increases tokens by 40 percent or removes a required fallback, the pull request should state why.

    NIST’s AI Risk Management Framework frames generative AI risk as an ongoing governance task. Your lint policy should therefore have named owners, versioned rules, documented exceptions, and a process for reviewing them.

    Put prompt linting into CI/CD pipelines

    Run the fastest checks where developers get feedback first, then apply stronger release gates as risk increases. GitHub Actions supports workflow jobs defined in YAML, which makes it suitable for a prompt repository alongside ordinary build checks. Review the GitHub Actions workflow syntax before standardizing the job layout.

    Start with local checks and pull requests

    Run linting in a pre-commit hook or editor task for immediate feedback. A VS Code extension can run the same rules before commit, reporting rule IDs, severity, and remediation without duplicating the linter’s logic. Local checks should feel close to zero latency, but teams should measure execution time rather than promise it.

    On every pull request, use automated static analysis to scan changed prompt files, schemas, and policy manifests. Regression fixtures and output validators provide the behavioral evidence that static checks cannot.

    Report the rule ID, severity, file, line, prompt version, and remediation guidance. A vague “prompt failed” status creates work for reviewers. A finding such as isolate-untrusted-context points to a decision someone can fix.

    Fail pull requests for critical security and schema violations. Use warnings for style preferences or early token-budget tuning, unless a route has a strict cost ceiling.

    Use pre-deployment gates for broader evidence

    Before deployment, pair linting with regression fixtures and output validators. Store the exact prompt version, model identifier, generation settings, test inputs, retrieved documents, tool responses, tenant settings, and conversation history that affect the result.
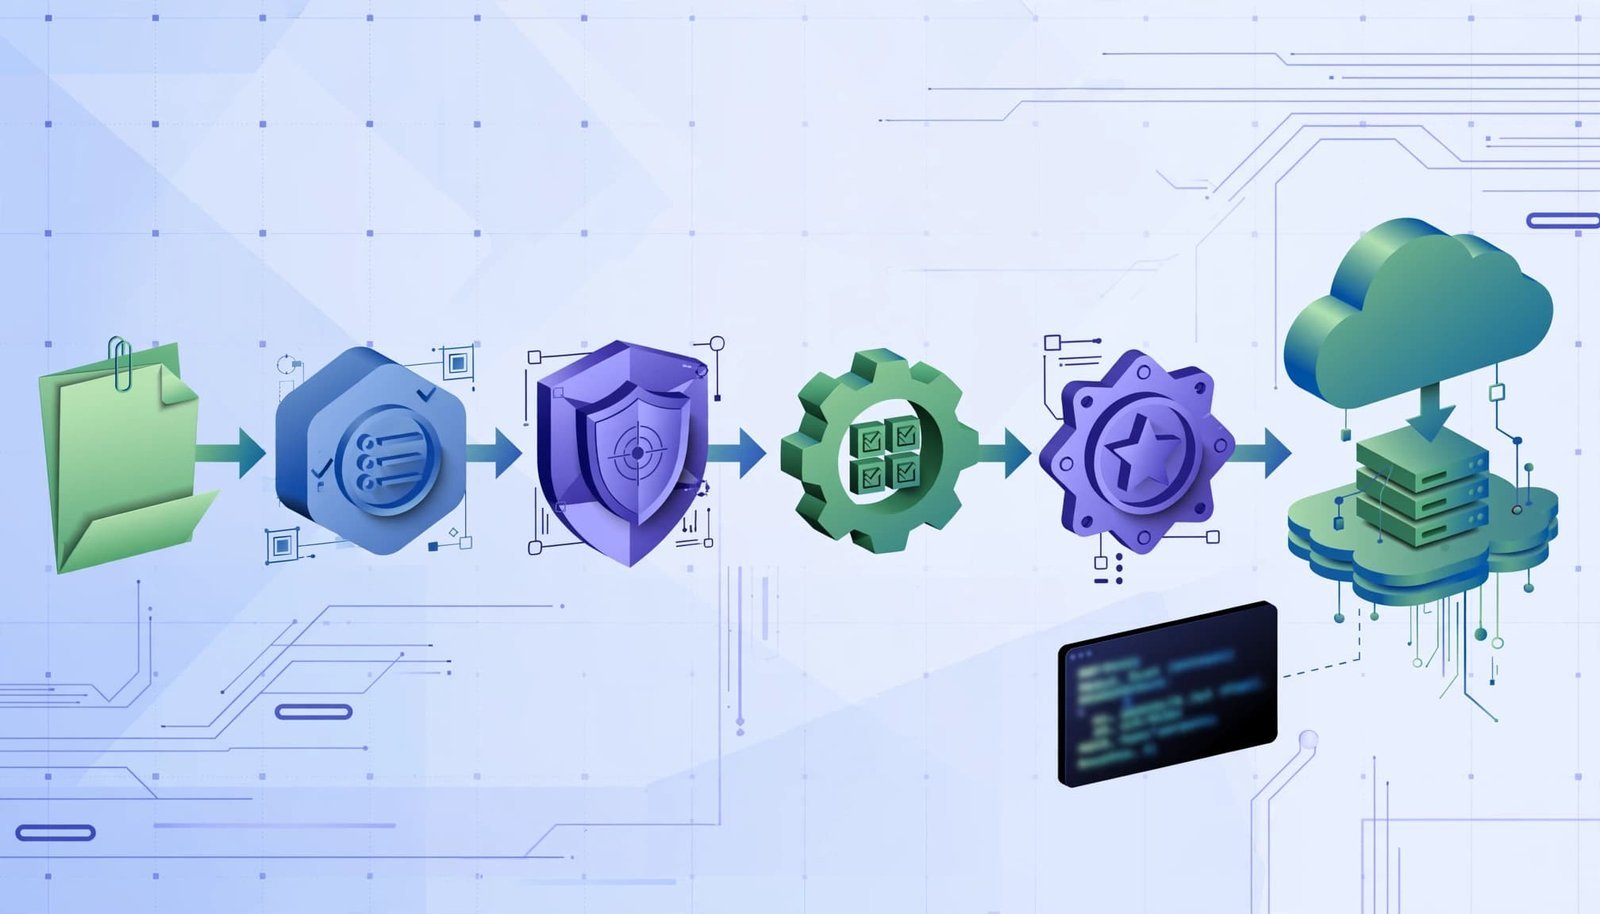
    Geometric stages show a file moving through checks into cloud deployment.

    Run a small high-risk suite on pull requests. Then run broader regression tests before release or on scheduled builds. CI artifacts should preserve failed inputs, scores, validator messages, and prompt versions without unnecessarily storing raw sensitive content.

    Test the runtime behavior linting cannot see

    Static analysis is one gate in a larger reliability system. Linting can verify structural correctness, but runtime tests show whether the model follows that structure in practice.

    Use fixtures that reproduce real failures

    A fixture should capture every input that affects a result. Include the user request, relevant retrieved documents, conversation state, tool responses, and tenant-level policy settings.

    Test happy paths, missing context, malformed tool results, refusal cases, boundary values, and adversarial content. Stable fixtures and stubbed external services help you reproduce a failure without depending on live systems.

    Code coverage cannot replace prompt testing. Coverage shows which application paths ran. It doesn’t reveal hallucination risk, fabricated claims, incorrect tool selection, unsupported answers, or format violations.

    Measure variation with risk-based thresholds

    Use deterministic assertions for fixed requirements, such as valid JSON, required fields, approved URLs, or prohibited phrases. For open-ended outputs, use a narrow semantic rubric and repeat important cases at the same model settings.

    A high-risk route might require every security and schema test to pass, plus a 95 percent pass rate across repeated core-task fixtures. Track latency, token use, lowest score, error count, and refusal quality against the prior release.

    PromptDoctor research describes a tool for detecting and correcting issues involving bias, vulnerability, and performance in developer prompts. Its PromptDoctor overview is useful context, but an auto-fix remains advisory and needs human review. It may remove a risky phrase while changing a product requirement, so it isn’t a substitute for security review.

    Apply the same standards to AI content directories

    Prompt linting matters for content products, not only agents and chatbots. If you publish a general AI tool directory, a complete AI tools list, or a comprehensive AI list, your prompts need source, category, and pricing rules.

    A page about best AI tools 2026, new AI tools 2026, or top-rated AI software should prohibit invented ratings and unsupported pricing. It should also distinguish a free AI tools list from a premium AI software list.

    Content and writing AI requests need tighter categories. An AI writing tools list may compare best AI copywriter tools, AI blog post generators, AI grammar checkers, and AI essay writing tools. Your prompt contract should require selection criteria, cited evidence, and clear disclosure when information is unavailable.

    Key takeaways

    • Treat prompts as versioned interfaces with explicit security, format, tool, and fallback requirements.
    • Use prompt linting to block recognizable unsafe patterns before deployment.
    • Keep static analysis separate from behavioral evals, schema validation, and runtime guardrails.
    • Store fixtures with the context that changes model behavior, then test failures you have actually seen.
    • Give critical findings hard release gates, while routing lower-risk warnings to review.

    Frequently asked questions

    Can prompt linting prevent every prompt injection attack?

    No. It can flag configured patterns and enforce safer prompt structure. You still need least-privilege tools, input handling, output validation, runtime monitoring, and tests against adversarial fixtures.

    What should fail a deployment immediately?

    Block releases for exposed secrets, successful injection tests, schema violations on machine-consumed output, unsafe tool permissions, and confirmed sensitive-data leaks. Style issues and small token increases usually belong in warnings unless they violate a route-specific policy.

    Should every prompt require JSON output?

    No. Use a schema when software needs predictable fields or the response triggers an action. Free-form content can use an editorial contract that checks source-grounding, prohibited claims, and semantic quality.

    Build safer releases with layered evidence

    Prompt linting makes unsafe or incomplete instructions visible before they become production behavior. It exposes known structural and policy problems, but it can’t prove safe runtime behavior on its own.

    Combine prompt linting with fixtures, behavioral evaluations, output validation, and monitored releases. Together, these layers make prompt optimization an evidence-based process, supported by lint findings, fixtures, output validation, and monitored releases. That layered evidence gives you a clearer basis for shipping prompt changes than a polished demo ever can.
  • Self-Consistency Prompts for Reliable Numerical Answers

    Self-Consistency Prompts for Reliable Numerical Answers

    A fluent numerical answer can still be wrong because one missed condition or arithmetic slip can derail the entire result. Self-consistency prompts reduce that risk by asking a model to solve the same problem through several sampled reasoning paths, then comparing their final answers.

    For large language models, self-consistency prompting compares multiple sampled solutions instead of trusting one polished response. This provides an agreement signal, but it doesn’t guarantee correctness. You still need validation rules for calculations, units, and source data.

    How self-consistency prompts work

    Self-consistency prompts extend Chain-of-Thought prompting with repeated sampling. Instead of accepting one completion generated through greedy decoding, you request multiple independent attempts and aggregate their results.

    The 2022 paper Self-Consistency Improves Chain of Thought Reasoning in Language Models proposed this approach as an alternative to selecting one likely token path. It performed well across arithmetic reasoning, commonsense reasoning, and symbolic reasoning tasks because different samples may avoid different mistakes.

    One prompt, several reasoning paths

    Give every sample the same problem, assumptions, and output format. Then vary the sampling process enough that the model can take distinct routes to the answer.

    For a numerical task, each response should expose a short calculation summary and finish with one machine-readable value. You don’t need a lengthy internal rationale. A clear list of equations, assumptions, and the final answer gives your application enough evidence to validate.

    Aggregate answers, not prose

    The important comparison happens at the final-answer level. If seven samples return 42, two return 40, and one fails to parse, 42 wins the majority vote.

    Google Research describes how majority voting can improve Chain-of-Thought results. However, matching answers are evidence of agreement, not mathematical proof. A shared misunderstanding of the prompt can still produce a confident, wrong majority.

    Blue and amber paths merge at a glowing central answer node.

    Self-consistency prompting versus standard chain-of-thought prompting

    Self-consistency prompting differs from standard Chain-of-Thought because it samples multiple reasoning paths instead of asking the model to reason once. Standard Chain-of-Thought can help with multi-step arithmetic, yet it still leaves you dependent on one sampled path.

    This approach retains the same reasoning-oriented instruction but repeats inference. Few-shot prompting supplies examples, while this method varies sampled solutions. Tree of thoughts explicitly explores branches, while this workflow samples independent completions. The difference is a decoding and aggregation workflow around the prompt during LLM inference.

    Greedy decoding has one chance to fail

    Greedy decoding tends to choose the highest-probability next token at each step. That makes outputs repeatable, but it can lock the model into an early bad assumption.

    For example, a model may subtract a discount before adding a required fee. If every next token follows that path, the final total remains wrong. Multiple sampled paths give the system a chance to test other interpretations.

    Majority voting needs normalized values

    Treat 1,250, $1250.00, and 1250 dollars as the same answer only after normalization. Remove currency symbols, standardize decimal precision, convert agreed units, and reject ambiguous values.

    A reliable parser should also preserve the raw response. You need it when a vote looks suspicious or an extraction rule starts failing after a prompt change.

    Agreement is useful only when every sampled answer refers to the same quantity, unit, date, and rounding rule.

    A numerical workflow you can implement

    Suppose you ask: “A service costs $240 per month. It rises 15%, then receives a $30 credit. What is the new monthly cost?” The correct calculation is 240 × 1.15 - 30 = 246.

    Ask for eight to twelve independent samples. Each should return a concise calculation and a final value in a fixed field, such as FINAL: 246.00. Self-consistency prompting votes over completed samples, while tree of thoughts branches and evaluates intermediate states.

    Use a compact prompt contract

    A 5C prompt contract is a compact piece of prompt engineering that keeps the task stable across samples:

    • Character: “Act as a careful financial calculations assistant.”
    • Cause: “Calculate the requested amount using the supplied figures.”
    • Constraint: “Do not invent fees, taxes, or assumptions. Preserve units and round only at the end.”
    • Contingency: “If information is missing, return INSUFFICIENT_DATA.”
    • Communication: “Return short calculation steps followed by FINAL: <number>.”

    This structure defines the job, limits, fallback behavior, and output shape. It isn’t a substitute for executable checks.

    Decide what to do with disagreement

    After parsing the outputs, group equivalent values and calculate the winning share. With 10 valid samples, an 8 to 2 split gives stronger operational confidence than a 4 to 3 to 3 split.

    Handle outcomes with explicit rules:

    1. Accept high-agreement answers only after deterministic checks pass.
    2. Retry malformed responses once, then record them as failed samples.
    3. Escalate split votes for recalculation with a different prompt or a human review.
    4. Reject results when samples use conflicting units, assumptions, or interpretations.

    A simple vote count is useful. Yet your system should also log the second-most-common answer, parse failures, and the reasoning summaries that produced each result.

    Tune temperature and sample size with evidence

    Temperature decoding controls how much randomness enters token sampling. At very low settings, your samples may become near duplicates. At high settings, they can drift into weak reasoning or inconsistent formats.

    The practical goal is diverse responses with useful variation. You want independent attempts at the calculation, not decorative paraphrases or random guesses.

    Start with a measured baseline

    Run a fixed evaluation set at one modest temperature and compare it with lower and higher settings. Keep the model, prompt, token limit, and parser unchanged while you test.

    For each configuration, record model accuracy, agreement rate, malformed-output rate, median latency, and token use. A setting that raises agreement but lowers accuracy isn’t an improvement.

    Add samples until gains flatten

    A larger sample size raises inference cost and tail latency. Start with a smaller batch, evaluate it against known answers, and add samples only when they improve outcomes enough to justify the expense.

    GSM8K is useful for testing arithmetic reasoning because it contains 8.5K grade-school math word problems. Still, also create fixtures that match your own work, including tax calculations, subscription proration, inventory totals, or campaign-budget math.

    Build a production pipeline that controls cost

    A production workflow shouldn’t send every request through the largest possible voting batch. Choose the batch size based on computational cost, risk, and latency. A one-line percentage calculation may need fewer samples than an answer that affects a customer invoice or financial report.

    Run independent generations in parallel during LLM inference when your provider and budget allow it. Then use a fixed decision graph: generate, parse, normalize, validate, vote, verify, accept or escalate.

    Put exact checks in code

    Software should verify facts it can prove. Before an LLM judge sees an answer, validate numeric syntax, required fields, accepted units, date formats, known inputs, and arithmetic identities.

    For the $240 example, your application can independently recompute the total. If a candidate says $246 but its shown equation equals $216, flag the mismatch. Deterministic validation catches failures that majority voting may miss.

    Use early stopping carefully

    If the first five valid samples agree and pass a calculation check, additional calls may add little value. Early stopping can reduce cost and latency, but only use it after testing the policy on representative data.

    Cache stable calculations when inputs, prompt version, model, and settings match. Keep prompt templates, sample settings, parsers, and fixtures under version control. Otherwise, you won’t know whether a later accuracy change came from the prompt, model, or aggregation code.

    Server rack with flowing data paths, result clusters, and a disagreement warning.

    Use Universal Self-Consistency for open-ended work

    Numerical values are easy to group. Free-form text generation is harder to compare because correct answers can use different wording.

    Universal Self-Consistency, proposed in 2023, asks an LLM to compare several candidate responses. It then chooses the answer that best meets stated criteria. Unlike tree of thoughts, it selects among completed candidates rather than evaluating an explicit search across branches.

    Give the judge a narrow rubric

    Provide the original request, allowed source context, candidate outputs, and one clear scoring task. For free-form text generation, ask whether each material claim has support. For a numerical explanation, ask whether the calculation matches the supplied values.

    Require structured output such as a winner ID, confidence category, evidence, and failure reasons. Don’t ask the judge to reward confidence, length, or polished formatting unless those traits matter to the task.

    Test the judge for bias

    LLM judges can prefer the first answer, longer prose, or writing that resembles their own style. Therefore, rotate candidate order in evaluation runs and compare concise answers with longer equivalents.

    For open-ended questions, Universal Self-Consistency can improve candidate selection. Evaluate universal self-consistency against human-reviewed examples before using it for high-impact content or financial claims. It still needs calibration, especially when factual accuracy matters.

    Evaluate reliability on your real use cases

    Accuracy alone hides useful failure patterns. Track how often the vote agrees with a known answer, how often samples disagree, how many outputs fail parsing, and what each accepted result costs.

    For high-risk routes, save stable fixtures for arithmetic reasoning, including the input data, prompt version, model settings, expected result, and validation rules. Run those fixtures again whenever you change a model, prompt, parser, or routing policy.

    Test beyond arithmetic benchmarks

    A general AI tool directory needs checks for duplicate domains, unsupported capability claims, stale pricing, and broken links. The same discipline matters for a complete AI tools list or comprehensive AI list.

    If you publish pages about the best AI tools in 2026, top-rated AI software, or new AI tools in 2026, treat ratings and product claims as facts that require evidence. Separate a free AI tools list from a premium AI software list rather than letting a model infer pricing tiers.

    Apply the method to content workflows

    Content systems also benefit from repeated evaluation of free-form text generation. Build fixtures for an AI writing tools list, best AI copywriter tools, AI blog post generators, AI grammar checkers, and AI essay writing tools.

    Use code to check required citations, exact counts, URLs, and numeric comparisons. Apply the same checks to tree of thoughts workflows, then use a narrow judge rubric to assess relevance and support. A model vote can prioritize the strongest draft, but it can’t verify a price or capability without dependable source data.

    Key takeaways

    Self-consistency works best when you treat it as a controlled inference pipeline, not a request to “try again.” Sample multiple paths, normalize final values, validate what code can verify, and use agreement to decide when an answer deserves acceptance.

    Low agreement is valuable information. It can expose missing assumptions, vague wording, unit conflicts, prompt defects, or a problem that needs a trusted external calculation.

    Frequently asked questions

    Does self-consistency guarantee a correct numerical answer?

    No. It raises the chance of selecting a correct answer when independent reasoning paths converge, but a model can repeat the same flawed assumption across samples. Check calculations with deterministic code whenever possible.

    How many samples should you generate?

    There is no universal number. Begin with a small batch, test it against representative fixtures, and increase the sample size only when accuracy gains justify added cost and latency.

    When should you avoid majority voting?

    Avoid direct voting when outputs cannot be normalized into equivalent answers, when inputs are missing, or when a small vote margin could affect money, safety, or compliance. Use deterministic verification, a constrained judge, or human review instead.

    Reliable answers need more than agreement

    A model’s first answer is a guess, even when it sounds certain. Repeated sampling gives you a stronger basis for trust by exposing agreement, disagreement, and malformed responses across several attempts.

    The most dependable systems combine that signal with explicit assumptions, code-based checks, measured thresholds, and clear escalation rules.

  • Prompt Contracts: Define Inputs, Outputs, and Failure States

    Prompt Contracts: Define Inputs, Outputs, and Failure States

    A fluent response from a large language model can still break your product. It may return malformed JSON, make an unsupported claim, edit the wrong file, or call a tool with unsafe arguments.

    Prompt contracts turn a loose instruction into a testable behavioral specification. You define what the model receives, what it may produce, what must remain true, and how the system responds when the request is incomplete or unsafe.

    That discipline moves your work beyond vibe coding and toward AI behavior you can inspect, test, version, and improve.

    Treat prompt contracts like API contracts

    A traditional API contract tells callers what to send, what they get back, and which errors to expect. Large language models are probabilistic, so a prompt contract cannot force identical wording. It can still define important boundaries and invariants, conditions that must remain true.

    Replace implied requirements with explicit rules

    “Write a product comparison” leaves too much open. Prompt engineering clarifies intent, but application rules determine what the system can enforce. A useful contract states the allowed source material, target audience, required sections, word limit, output format, and unsupported actions.

    For a research assistant, you might require supplied sources before it makes a factual claim. For a coding agent, you might limit changes to named files. For a support bot, you might require a clarifying question when the account context is missing.

    The goal isn’t simply shorter prompts. It’s fewer assumptions and token efficiency that preserves necessary context.

    Separate the prompt from its enforcement

    Prompt wording establishes intent, but code must enforce requirements that software can verify. Your application should parse JSON, reject missing fields, restrict tool arguments, and block actions outside approved scope.

    Claude’s structured output documentation describes schema transformation and automatic validation helpers. Those capabilities reduce parsing failures, although they don’t prove the content inside a valid response is accurate. An API contract describes an interface, while application code still validates model output.

    A valid JSON object can still contain a fabricated answer. Structural validation and factual validation are separate checks.

    Define the five jobs of a contract

    A practical contract gives the model a bounded job and gives your application a reliable way to judge the result.

    State inputs and preconditions

    Inputs include more than the user’s latest message. Record the system instructions, retrieved context, conversation history, tenant settings, tool results, model settings, and any policy constraints.

    Preconditions say when work may begin. They should also establish invariants for valid work, such as required fields and allowed operating conditions. A travel assistant, for example, may need destination, date range, and traveler count. If any required field is absent, the contract should require a clarification rather than a plausible guess.

    Also define trust levels. User text, web pages, uploaded files, and tool responses can contain instructions, but they should never override your system rules.

    Specify outputs, evidence, and scope

    Your output schema should name required fields, permitted values, data types, and evidence requirements. An editorial workflow might return title, summary, claims, sources, and uncertainties. A coding workflow may return a patch plan, changed files, tests run, and unresolved risks. A behavioral prompt contract goes beyond a type contract or machine-enforced schema. The output schema defines shape, while invariants define behavior and protected conditions.

    Scope control is equally important. Tell an agent which repositories, directories, tools, and actions it may use. Then state the invariants, or conditions that must remain true, such as “do not change public API signatures” or “do not alter authentication rules.” Check permitted tools and actions against these conditions before allowing the work to proceed.

    An engineer stands beside a whiteboard divided into four workflow sections.

    Use a 5c prompt contract when you need a compact prompt contract

    The 5c prompt contract, described in a 2025 paper, is a compact prompt-engineering structure for routine interactions with less cognitive overhead. Its cognitive architecture organizes how a model receives a task, constraints, fallback behavior, and presentation guidance. It isn’t a literal reasoning trace, API schema, or substitute for executable tests.

    Character, Cause, and Constraint

    Character identifies the operating role, such as a procurement analyst or TypeScript test reviewer. Cause states the job and intended outcome. Constraint lists non-negotiable rules, including allowed data, prohibited claims, output length, file boundaries, and other invariants.

    For example, a marketing research prompt could instruct the model to act as an evidence-focused analyst, compare only supplied vendor records, and label unknown pricing as unavailable. That is more reliable than asking it to “find the best options.”

    Contingency and Calibration

    Contingency defines fallback behavior. It may require the model to ask a question, return an insufficient_context status, abstain, or escalate for review.

    Calibration adjusts tone, detail, and output shape. You might request concise executive language, a neutral editorial voice, or a JSON object that matches a schema. Concise output requirements can also improve token efficiency.

    Use 5C for focused, repeatable tasks. For repository edits, regulated decisions, or multi-step agents, add explicit tests, tool rules, and acceptance criteria around it.

    Build a fuller contract for AI-generated code

    Software tasks require more detail because small omissions can lead to broad and expensive changes. A fuller coding contract can extend a lightweight 5c prompt contract into eight sections: objective, preconditions, invariants, exact file scope, implementation contract, test-first specification, acceptance criteria, and anti-patterns.

    The prompt contract should not be confused with API schemas, type contracts, or validators. Those tools enforce machine-checkable structure, while the coding contract defines intent, scope, invariants, acceptance criteria, and prohibited changes.

    Set the objective, boundaries, and invariants

    Write one outcome that a reviewer can recognize. “Add server-side validation for invitation expiry” is clearer than “improve invitations.”

    Then name the permitted files and dependencies. Use scope control to state what must not change, including database migrations, existing endpoint shapes, or permission checks. These invariants protect endpoint behavior and authorization rules. An agent should propose extra files before touching them, not decide unilaterally.

    List anti-patterns to make hidden risks visible. You might prohibit broad refactors, new packages, disabled tests, silent error handling, or changes to generated files. The contract should also prohibit changes to production code outside the approved scope.

    Make acceptance criteria executable

    Acceptance criteria should describe observable behavior. Require compilation, formatting, linting, type checking, unit tests, and static analysis as separate checks within a verification gate. Use test-driven prompting to define observable tests or a test plan before implementation. Ask for Arrange-Act-Assert tests that exercise public behavior rather than duplicate internal implementation details.

    For a function with many branches, require a test plan before code, including relevant edge cases. However, reviewing the patch, test fixtures, and command results is different from evaluating hidden algorithmic reasoning. Don’t treat private model reasoning as test evidence, and avoid unnecessary cognitive overhead during review.

    A contract becomes useful when a failed test points to a requirement that someone can fix. Clear anti-patterns also help reviewers identify prohibited behavior without guessing.

    Validate outputs and define graceful failure

    Production-grade reliability comes from a pipeline around the model, not prompt text alone. Validation catches hard failures before an answer reaches a customer or autonomous tool.

    Run deterministic checks first

    Use input validation for incoming fields and tool arguments. Check required keys, enums, string lengths, numeric ranges, URLs, citation fields, and permitted tool names with JSON Schema, Zod, or comparable validators. These checks are inexpensive and explainable, including for edge cases such as boundary values and missing fields.

    Make structural validation the first verification gate. If wording may vary, use a narrow semantic rubric afterward. A judge can assess whether an answer follows supplied policy or addresses the user’s goal. It should not decide whether valid JSON has the required keys.

    Structured-output and function-calling patterns help you connect model responses to predictable application behavior across common LLM providers. Keep semantic evaluation separate from factual verification when claims require evidence.

    Distinguish bad answers from transient errors

    Clear failure modes separate transient provider errors from invalid answers. A timeout, rate limit, or temporary provider failure may justify a bounded retry with backoff. An invalid schema, unsafe tool call, or unsupported claim needs a repair instruction, fallback response, or human review path.

    A bounded repair loop can follow an actionable repair instruction. It shouldn’t silently retry unsafe or unsupported output. Track token efficiency when measuring retry costs, and confirm invariants still hold after validation or tool execution.

    Failure states should be named and actionable:

    • invalid_input means required fields are absent or malformed.
    • insufficient_context means the available material cannot support a reliable answer.
    • policy_refusal means the request violates a defined safety or access rule.
    • tool_unavailable means a dependency failed after the allowed retry limit.
    • validation_failed means the response did not meet its output contract.
    A branching pipeline shows successful processing and an error loop for repair.

    Protect contracts against ambiguity and injection

    Ambiguity is a product condition, not a model defect. Your contract should state when the model may infer a reasonable default and when it must request clarification.

    A 5c prompt contract uses its Contingency element to define clarification, abstention, or escalation behavior.

    Keep untrusted instructions in their place

    Prompt injection occurs when content attempts to override the model’s intended behavior. A webpage might say “ignore all previous instructions,” while an uploaded document may try to extract protected data.

    Define invariants so external content can’t override system rules or protected behavior. The OWASP prompt injection guidance treats this as a core risk for LLM applications. Treat external content as data, delimit it clearly, limit tool permissions, and validate any action before execution.

    Input filtering helps, but it can’t solve the problem by itself. Your architecture needs least-privilege tools and approval gates for consequential actions.

    Refuse accurately and without invented success

    A contract should prohibit the model from claiming it sent an email, changed a record, completed a purchase, or verified a fact unless a trusted tool result confirms it.

    When a tool fails, use a bounded, permission-aware repair loop. Never use it to retry a prohibited action indefinitely. Return a user-appropriate status without exposing secrets, internal stack traces, or access details. OWASP’s prevention cheat sheet also recommends input sanitization alongside output monitoring and validation.

    Version contracts and log the evidence

    Prompt text is release behavior. Store your schema, examples, fixtures, model settings, and evaluation rules in version control. For compact workflows, version the 5c prompt contract and preserve its stable cognitive architecture across releases.

    Review behavior changes, not only wording

    A pull request should reveal whether you changed source-grounding rules, allowed tools, refusal behavior, or output fields. Use test-driven prompting by versioning prompts and behavioral tests together. Otherwise, reviewers can’t tell whether a new prompt still meets the old contract.

    Run the same fixed fixtures before and after a change. Compare the results against your acceptance criteria, including invariants such as required fields and refusal behavior. For variable tasks, measure pass rate, lowest score, latency, token use, token efficiency, and error count across repeated executions.

    Capture useful observability without leaking data

    Log the contract version, model identifier, validator outcome, tool name, tool result status, latency, and token counts. This evidence helps you locate whether a failure began in retrieval, generation, parsing, or tool execution.

    Logging evidence doesn’t mean storing raw sensitive prompts and completions by default on sensitive routes. Redact personal data, access tokens, account numbers, and health details. Keep detailed traces access-controlled and retain them only as long as your incident process requires.

    Apply prompt contracts to AI content recommendations

    Content systems need contracts because polished prose can disguise weak research. For a general AI tool directory, contract invariants should cover duplicate domains, evidence-backed categories, current links, and dated pricing. A complete AI tools list or comprehensive AI list should flag incomplete records instead of presenting them as current.

    A page about the best AI tools 2026, top-rated AI software, or new AI tools 2026 needs stated selection criteria and attributable evidence. Distinguish a free AI tools list from a premium AI software list, and never turn sponsored placement into an objective ranking.

    Content and writing AI require task-specific rules. An AI writing tools list shouldn’t use the same rubric as the best AI copywriter tools, AI blog post generators, AI grammar checkers, or AI essay writing tools. Define whether you’re judging factual grounding, brand control, grammar accuracy, citation quality, privacy terms, or workflow fit.

    Key Takeaways

    • Treat each prompt as a versioned interface with defined inputs, outputs, assumptions, tool limits, and failure states.
    • Put fixed requirements and invariants in code, including schemas, allowed actions, factual sources, and sensitive-data checks.
    • Use clarifying questions, abstention, and bounded retries instead of guesses and silent loops.
    • Test happy paths, missing context, boundary cases, tool failures, and adversarial inputs against clear acceptance criteria before release.
    • Keep logs that connect model behavior to the contract version without storing sensitive content carelessly.

    Frequently Asked Questions

    What is a prompt contract?

    A prompt contract is a structured specification for an LLM interaction. It defines the task, accepted inputs, preconditions, output format, behavioral limits, validation rules, and fallback behavior.

    It doesn’t make a model deterministic. It makes the system’s expected behavior clearer and easier to test.

    How do prompt contracts prevent vibe coding failures?

    They replace vague requests with scope limits, invariants, acceptance requirements, and explicit error handling. For coding agents, that means you can restrict file changes, require tests, and reject changes that violate public interfaces.

    The surrounding application must still validate the result. A prompt alone can’t stop a bad parser, a broken tool, or an unsafe permission model.

    Should every prompt use JSON Schema?

    No. Use a schema when downstream software needs predictable fields or when the output triggers an action. Free-form writing can use an editorial contract with source rules, prohibited claims, and semantic evaluation instead.

    You can also mix both approaches. Return structured metadata for validation while keeping the final customer-facing prose flexible.

    Build for accountable AI behavior

    Prompt contracts help you stop treating a polished response as proof that an AI workflow worked. A 5c prompt contract suits compact tasks, while a fuller contract offers more control. Both can define the job, constrain risk, validate results, and preserve evidence when something fails.

    The strongest contract is one your application can test and your team can review, balancing clarity, reliability, and token efficiency.

  • Prompt Observability for Production LLM Debugging

    Prompt Observability for Production LLM Debugging

    With this visibility, you can spot a production LLM failing after a harmless-looking prompt edit, even after thousands of flawless requests. It may produce invalid JSON, cite nonexistent facts, call the wrong tool, or refuse a valid request.

    Prompt observability gives you the evidence to connect that failure to the exact request path, prompt version, model call, retrieval result, and deployment that preceded it. You need more than error logs because fluent output can hide a broken application contract.

    The goal is to make every important generation inspectable across AI applications without turning your telemetry data into a store of sensitive customer conversations.

    Why Production LLM Failures Need Traces

    Traditional application monitoring tells you whether an endpoint returned a 200 response, timed out, or threw an exception. That remains useful, but it can’t show whether the answer was grounded, whether a prompt changed, or why an agent selected a high-risk tool.

    Traditional monitoring misses model behavior

    A response can be technically successful and still damage the product. For example, a support assistant may return HTTP 200 while inventing a policy exception. A content workflow may finish normally while producing an article with broken citations.

    You need to measure behavioral outcomes alongside infrastructure health. Track error rates, schema failures, refusals, unsupported claims, retrieval sufficiency, tool errors, and evaluation scores. Then segment them by model, route, tenant, language, and prompt version.

    A successful API response only proves that the model answered. It doesn’t prove that the answer met your product’s factual, safety, or formatting requirements.

    A request is an execution graph

    Most serious AI applications don’t make one model call. A user request may trigger classification, retrieval, prompt assembly, generation, tool calls, a second model call, output validation, and a database write.

    When you view that work as a connected trace, you can locate the first bad decision. Perhaps retrieval returned stale documents. Perhaps the agent chose an unavailable tool or bypassed required approval workflows for a high-risk action. Perhaps the model output valid prose but violated the response schema.

    A branching trace graph with model, retrieval, and tool pathways on a dark blue background.

    What Prompt Observability Should Capture

    Your records must make a production incident reproducible. Capture the request context, but separate what you need for diagnosis from content you should not retain.

    Prompt, model, and deployment identity

    Assign an immutable ID to every system prompt, template, and few-shot example set. Record the prompt version, model provider, model name, temperature, top-p, output schema version, retrieval configuration, and application release.

    A temperature change is a new experiment. So is a changed chunk size, different reranker, altered tool definition, or updated evaluator rubric. Use approval workflows for changes to model settings, retrieval, and evaluator configuration. Without these fields, a score drop leaves you guessing whether the prompt, model, or surrounding pipeline changed.

    Git-based prompt management makes review and branching practical. Keep prompt files, test fixtures, and evaluation contracts near the application code. A pull request should show what behavioral promise changed, not only which sentence changed.

    Tokens, latency, cost, and error signals

    Token usage affects both response time and spend. Measure prompt tokens, completion tokens, total tokens, cache use where your provider exposes it, and end-to-end latency. Prompt and completion tokens influence latency and cost, while cache use and provider pricing determine how those measurements support cost control. Also retain latency for each span because a slow retrieval or tool call can look like a slow model.

    Datadog’s documented agent observability metrics include span and error counts, token usage, latency, plus tags for model, provider, service, and version. Its cost calculation uses provider pricing with token values attached to spans, so token counts alone shouldn’t become assumed dollar amounts.

    SignalWhat it can revealUseful breakdown
    Total tokensPrompt bloat or runaway agent loopsPrompt version and route
    End-to-end latencySlow user experienceRetrieval, model, and tool spans
    Error ratesProvider or parser failuresModel, region, and release
    Refusal rateOverly restrictive instructionsIntent and customer segment
    Quality scorePrompt drift or weak contextVersion and traffic cohort

    Watch distributions as well as averages. Stable evaluation metrics can conceal a sharp failure rate for one language, customer tier, or tool path. This often indicates prompt drift in a specific segment.

    Use OpenTelemetry for LLM and Agent Traces

    For practical llm observability, OpenTelemetry gives you a vendor-neutral way to carry trace context across services. Instead of isolated logs, you get parent-child relationships between the request, retrieval from vector databases, model call, tool invocation, and downstream action.

    Build spans around meaningful work

    Start one trace at the user-facing request. Create trace spans for prompt rendering, vector search, reranking, LLM generation, tool calls, structured-output parsing, policy checks, and external writes.

    Attach stable attributes that help you filter incidents. Include service name, environment, model provider, model name, prompt version, route, and tenant category where permitted. Add status and error information at the span that actually failed. Include guardrail monitoring events when policy checks influence the response.

    The OpenTelemetry GenAI semantic conventions repository covers spans, metrics, and events for GenAI clients and MCP-related activity. Because these conventions continue to develop, map your internal fields deliberately and avoid binding critical dashboards to unstable names without a migration plan.

    Capture content selectively

    The OpenTelemetry guide to GenAI observability describes telemetry for model identity, token counts, and optional capture of prompts, completions, tool calls, and tool results. Optional is the important word.

    Default to metadata and hashes for sensitive routes. Redact email addresses, account numbers, access tokens, health details, and secrets before exporting telemetry data. Use sampled, access-controlled content capture for incident investigation, with privileged access managed through approval workflows, short retention, and documented audit trails.

    For multi-step agent observability, record both the selected tool and its outcome. Require approval workflows before consequential agent actions. A hallucinated answer may begin with a tool that returned no data, timed out, or received malformed arguments.

    Treat Prompts as Release Artifacts

    Prompt text is executable product behavior. It needs the same review history, audit trails, and rollback path as application code.

    Keep immutable versions and labels

    Prompt versioning starts with immutable saved versions and clear ownership. Require approval workflows before a prompt version enters a release candidate.

    Store each saved prompt version permanently. Use a production label or release tag that points to one exact version, rather than editing a live prompt in place. Your trace should record both the immutable version and the label used at runtime.

    That record lets you compare incident traffic before and after a deployment. When production traffic shows more hallucination reports after a label changes, inspect the prompt diff and use approval workflows for the production-label change.

    Langfuse’s prompt CI/CD guidance describes immutable versions, golden-dataset validation, CI gates, weighted rollout, and rollback by repointing a label. Rollback authorization should also follow approval workflows. The workflow matters more than the platform: every release needs a known version, test evidence, and a quick reversal route.

    Branch experiments without contaminating production

    Use Git branches for competing prompt approaches. Version control preserves review history, while git-based prompt management keeps each change traceable. A branch might tighten source-grounding instructions, while another changes tool-selection rules.

    Use approval workflows for pull-request review before merging either approach. Record system prompts, prompt templates, few-shot examples, fixtures, and generation settings for each candidate.

    Run each candidate against the same fixed fixtures and generation settings before comparing results. Inspect outputs in a prompt playground before experiment promotion, then use approval workflows to decide which candidate advances. A git-based prompt management process keeps those decisions connected to the tested changes.

    For an AI content product, these fixtures should reflect actual risk. A general AI tool directory may need checks for duplicate domains, unsupported category claims, stale pricing, and broken links. A complete AI tools list or comprehensive AI list needs evidence for every claimed capability.

    The same discipline applies to pages that recommend the best AI tools in 2026, list top-rated AI software, or announce new AI tools for 2026. You should reject invented ratings and distinguish a free AI tools list from a premium AI software list. A final git-based prompt management review can confirm those safeguards before release.

    Evaluate Quality Before and After Release

    Automated prompt evaluation catches quality regressions that traces alone cannot classify. However, an evaluation score is a measurement, not a verdict.

    Use code for facts software can prove

    Run deterministic checks before calling an evaluator model. These automated evaluations can validate JSON, required keys, data types, allowed tool names, tool calls, numeric ranges, citations, prohibited phrases, and PII patterns.

    This reduces evaluation cost because obvious failures never reach a judge. It also makes the result actionable. A missing sources field has a different owner and fix from a response that sounds helpful but fails to answer the user’s goal.

    For content workflows, validate required sources first. Then assess whether the generated claims are supported by those sources. That distinction matters for an AI writing tools list, a comparison of the best AI copywriter tools, AI blog post generators, AI grammar checkers, or AI essay writing tools.

    Use git-based prompt management to store evaluation fixtures near the application code. Put these checks in the regression suite and make them part of automated evaluations before release. Track evaluation metrics such as pass rates, quality scores, and judge agreement separately.

    Make LLM-as-a-judge rubrics narrow

    An LLM-as-a-judge workflow works when the judge receives the user task, relevant context, candidate output, a narrow rubric, and a required structured response. Ask one question per score. “Every material claim is supported by supplied context” is measurable. “Be excellent” is not.

    Use pointwise scoring to monitor a single production response. Use pairwise comparison when selecting between prompt versions. In pairwise tests, swap output order to expose position bias. Also test shorter and longer answers with the same facts, because judges can reward verbosity.

    Protect evaluation-dataset changes with approval workflows. Store rubric versions through git-based prompt management, keeping them near the application code and evaluation fixtures. Require approval workflows for rubric changes and separate approval workflows for judge-model changes.

    Log the evaluator prompt, judge model, generation settings, retrieval context, thresholds, and rubric version with every result. Calibrate scores against a frozen, human-reviewed dataset intended to detect performance regressions. Human review should focus on high-impact routes, borderline decisions, and cases where judges disagree. Use approval workflows for human review and release approval.

    Follow a Repeatable Production Debugging Workflow

    An incident becomes manageable when prompt observability supports the same evidence chain every time.

    Start with the customer symptom

    Begin with a concrete report: malformed output, a refusal, a wrong tool call, unsupported advice, rising cost, or slow responses. Identify the trace IDs and isolate a time window around the first observed change. Use approval workflows to document the initial triage and assign ownership.

    Next, compare the affected production traffic against a healthy baseline. Filter by prompt version, model, release, route, language, retrieval source, and tool path. A comparison across those dimensions often separates a broad provider problem from one bad deployment.

    An engineer reviews trace cards beside a notebook and monitor in a secure workspace.

    Find the first failing span

    Inspect the trace in execution order. Did retrieval lack relevant context? Did the prompt renderer omit a policy block? Did the model call produce invalid structure? Did a tool return an error that the agent ignored?

    Classify the failure before changing the prompt. Include performance regressions in quality, latency, or cost that appeared after deployment. If context is insufficient, label it as a retrieval failure. If retrieved evidence is sound but the answer contradicts it, investigate generation behavior. If an agent had correct information but chose an unauthorized action, review its tool policy and argument validation. When evidence points to a bad release, use approval workflows to authorize a rollback.

    Then reproduce the request with redacted fixtures and stubbed dependencies. Approve any prompt or configuration change through approval workflows after confirming the failure mode. Add the case to your regression suite, then record the post-incident fix in approval workflows. A fixed incident that never becomes a test case will return under a different input.

    Key Takeaways

    • Treat prompts, model settings, retrieval configuration, and evaluator rubrics as versioned release artifacts, with approval workflows for prompt and model changes.
    • Trace the whole request graph, including retrieval, generation, validation, tool calls, and downstream actions.
    • Track token use, latency, errors, cost, and quality scores by prompt version rather than in aggregate.
    • Use deterministic validators for fixed rules, then automated evaluations with calibrated LLM judges for subjective quality.
    • Capture sensitive content sparingly and redact before export. Use approval workflows for sensitive telemetry and tool actions, retaining only what incident response requires.

    Frequently Asked Questions

    What is the difference between this telemetry approach and standard monitoring?

    Standard monitoring tracks service health, exceptions, latency, and resource use. This telemetry approach connects those signals to prompt versions, model settings, token usage, retrieval context, outputs, evaluations, and tool behavior.

    You need both. A model request can succeed at the infrastructure layer while failing the product contract.

    How do you detect prompt drift in production?

    Use prompt versioning to compare quality, refusal, schema-failure, latency, and token distributions across immutable releases. Segment results by traffic type because a broad average can hide a serious regression in one route.

    Production samples should feed back into a human-reviewed evaluation dataset. Re-run that dataset whenever you change prompts, models, retrieval, evaluator rubrics, or output schemas.

    When are approval workflows required for sensitive or high-impact prompt changes?

    Use approval workflows before shipping prompt edits that could change user outcomes, data handling, or safety behavior. Require approval workflows for model changes, then authorize production rollout or rollback through them.

    Build Evidence Before You Change the Prompt

    The fastest fix is rarely the first prompt rewrite. prompt observability lets you locate the failing version and span before you change behavior under pressure.

    When prompts, traces, evaluations, release records, and approval workflows point to the same cause, you can roll back safely and test a focused repair.

  • LLM as a Judge Prompts for Reliable AI Evaluation

    LLM as a Judge Prompts for Reliable AI Evaluation

    A model can produce fluent nonsense, and a basic pass or fail check often won’t catch it. LLM-as-a-Judge evaluation gives you a practical way to assess quality at scale, as long as you define quality before asking a model to score it.

    A sound evaluation methodology for automated evaluation combines a judge model’s prompt, rubric, test set, and validation process. This supports model alignment with your defined quality standard.

    A reliable system separates subjective judgment from checks that code can prove.

    Key Takeaways for Consistent Evaluation

    • An LLM judge should receive the task, relevant context, candidate output, a narrow rubric, and a required structured output.
    • Use code for objective rules such as JSON validity, required fields, citation presence, policy terms, and numeric calculations.
    • Treat a metric score as a measurement that needs calibration against a human-reviewed dataset, not as unquestionable truth.
    • Use single-output scoring to monitor one generated answer. Run pairwise comparisons with swapped output order to reveal position bias.
    • Log the evaluator prompt, judge model, retrieval context, thresholds, and generation settings with every result.

    A vague instruction like “rate this answer” measures the judge’s personal preference. A bounded rubric measures a defined standard.

    What an LLM Judge Actually Evaluates

    An LLM-as-a-Judge workflow asks one model to assess output created by another model or system. The judge receives evidence, applies stated criteria, and returns a score, label, or comparison result.

    This approach is useful when the target quality has human elements. Helpfulness, clarity, tone, faithfulness to source material, and whether a response addressed a user’s goal all require interpretation.

    The four inputs your prompt needs

    A dependable evaluation prompt has four slots:

    1. Task or user request, which states what the original system needed to do.
    2. Relevant context, such as retrieved passages, a policy document, tool results, or a brand brief.
    3. Candidate output, which is the answer, action plan, or tool call under review.
    4. Rubric and response schema, which define the judgment and output format.

    A reference answer can sit alongside these inputs when an authoritative expected answer exists. Langfuse’s LLM-as-a-Judge documentation uses this same pattern: evaluation criteria, context, output, and an optional reference answer.

    Quality criteria must be observable

    Avoid criteria such as “be excellent” or “make it engaging.” They invite inconsistent scoring because the judge must invent the standard.

    Write criteria that point to visible evidence instead of vague instructions in a scoring rubric. For a RAG assistant, “every factual claim is supported by supplied context” is testable. For an agent, “the selected action matches the user’s stated goal and does not exceed the allowed permissions” is also testable.

    Each rubric item should answer one question. When accuracy, tone, completeness, and safety appear inside one score, you can’t tell what broke after a regression.

    Single-Output Scoring and Pairwise Comparison

    You have two main ways to ask a judge model for a decision. In an LLM-as-a-Judge workflow, select the format based on the product decision you need to make.

    Score one response against a fixed rubric

    Single-output scoring, also called pointwise evaluation, assigns a rating to one answer. It works well for monitoring production traffic because there may be only one generated response.

    Evaluation typeWhat the judge seesBest use
    Reference-free scoringRequest, context, response, rubricHelpfulness, tone, groundedness
    reference-based evaluationRequest, response, expected answer, rubricFactual tasks with known answers
    Binary classificationInputs plus pass criteriaPolicy checks and release gates
    Ordinal scoringInputs plus anchored scaleTracking quality trends over time

    An anchored metric score is more useful than an uncalibrated number. For example, a faithfulness score of 1 could mean the answer contradicts or invents unsupported claims. A 3 could mean it is mostly grounded but includes a minor unsupported statement. A 5 could require that all material claims are supported.

    Compare two candidates when choosing a winner

    Pairwise comparison shows the judge two outputs for the same request and asks which one better meets the rubric. This is often more stable for model selection, prompt experiments, and editorial rewrites because the judge makes a relative decision.

    Use it when you need to choose between prompt version A and prompt version B. Don’t use it as your only production metric, because a winner can still be poor in absolute terms.

    For a fair comparison, run the same case twice. Present A first in one trial and B first in the next to expose position bias. Record a tie when the order changes the winner.

    Build an LLM as a Judge Prompt That Holds Up

    A reusable evaluation prompt gives the judge model a constrained job. It names the role, presents inputs in stable labels, defines the scoring rubric, and demands a parsable answer.

    Require evidence before a score

    Ask the model to identify evidence in the candidate response and supplied context before it assigns a label. This makes faulty judgments easier to audit, even though the explanation itself isn’t proof that the score is correct.

    Use this pointwise template for grounded answers:

    You are evaluating an AI response.
    Score only the stated criteria using the supplied context.
    Identify unsupported claims before scoring faithfulness.
    Return valid JSON with score, verdict, evidence, and failure_reasons.
    Don’t reward length, formatting, or confidence unless the rubric requires them.

    Then provide the request, retrieved context, candidate answer, and score anchors under consistent field names. Keep context delimiters clear so the judge doesn’t mistake retrieved text for instructions. Use few-shot prompting only when rubric boundaries are genuinely ambiguous, not to decorate every prompt.

    Keep the response schema small

    Structured output reduces parsing failures and makes dashboards more useful. A response with a score, pass flag, short evidence list, and failure category usually gives you enough to act.

    For example, an agent judge could return:

    • decision: pass, fail, or review
    • goal_match_score: 1 through 5
    • policy_violation: true or false
    • unsupported_assumption: true or false
    • reason: no more than 60 words

    Don’t request a long essay unless a reviewer will read it. Long rationales increase cost and can obscure a simple failure signal.

    Use G-Eval Steps and Few-Shot Examples Carefully

    Some criteria need a more deliberate assessment process. G-Eval uses ordered steps and form filling instead of asking for an unstructured opinion.

    Turn the rubric into ordered evaluation steps

    The G-Eval research found that a G-Eval framework using GPT-4 correlated more closely with human judgments than earlier NLG evaluators. Its method uses chain-of-thought prompting and a form-filling approach. In production, expose concise evaluation steps and structured evidence without requesting or storing private reasoning.

    You can adapt the idea without exposing a lengthy internal rationale. State a short sequence:

    1. Determine the user’s intent.
    2. List claims in the candidate response.
    3. Check each claim against the supplied context.
    4. Assess whether the answer directly resolves the intent.
    5. Assign a score using the rubric anchors.

    This evaluation methodology prevents a judge from jumping straight to a polished but unsupported answer. Still, it doesn’t remove model variance, so validate it against human labels.

    Add examples only for hard boundary cases

    Few-shot prompting helps when your team has a specific standard that words alone don’t capture. In those cases, few-shot prompting works best with two to four labeled examples showing the difference between adjacent scores.

    Use edge cases, not obvious successes. A useful example might show a response that’s accurate but incomplete, followed by a score of 3 and a short explanation. Another can show a concise answer scoring higher than a longer answer because it answers the request without unsupported detail.

    Examples can also inject bias. If every high-scoring example is long, heavily formatted, or written in one voice, the judge may copy that preference.

    Detect Bias and Judge Variance Before Release

    LLM-as-a-Judge systems are sensitive to prompt framing, model family, output order, and surface style. Research associated with MT-Bench and Chatbot Arena identifies position bias, verbosity bias, self-preference bias, and limited reasoning in these systems. Review the MT-Bench analysis of judge bias before using scores as release gates, and test whether few-shot prompting introduces style or length preferences.

    Test position, verbosity, and self-preference

    Placement can cause the first or second answer to win more often. Length can earn rewards even when extra text adds no value. Self-preference bias can appear when a model favors writing similar to its own outputs.

    Build counterfactual tests. Take the same answer and create a shorter version with identical facts. Swap candidate positions for a pairwise comparison, then compare outputs from different generation models when possible.

    A trustworthy judge should give similar results when irrelevant presentation details change, showing model alignment with your team’s standard. When it doesn’t, revise the rubric and examples before changing your product.

    Calibrate against human-reviewed cases

    Create a frozen evaluation dataset from examples your team has labeled through human evaluation. Include routine cases, failures, adversarial prompts, ambiguous requests, and examples near the pass threshold.

    Review category-level disagreement, not only the average metric score. A judge that agrees on easy answers but misses safety failures isn’t ready for automated release decisions.

    Human review belongs at the boundaries: high-impact decisions, low-confidence outputs, and cases where two evaluators disagree.

    Combine Deterministic Checks With LLM Judgments

    A judge model is poor at tasks that software can verify exactly. Let each component handle the work it can perform reliably.

    Put hard requirements in code

    Use deterministic validators before invoking a judge for requirements such as:

    • Valid JSON, required keys, schema types, and permitted tool names
    • Exact word or character limits where the product requires them
    • Citation URLs, required disclaimers, forbidden terms, and PII patterns
    • Arithmetic totals, dates, identifiers, and database lookup results

    This reduces cost because clear failures never reach the judge. It also makes your evaluation easier to explain to an engineer, editor, or client.

    For content workflows, a validator can confirm that an article includes supplied sources. The LLM judge can then assess whether those sources actually support the claims.

    Use a decision graph for agents and RAG

    A Directed Acyclic Graph, or DAG, gives complex evaluation a fixed decision path. Each node receives a defined input and sends a clear result to the next relevant node.

    For example, RAG evaluation can start with a context-sufficiency check. If retrieval lacks the needed facts, label the outcome insufficient_context rather than blaming generation. Once relevant context is confirmed, use a groundedness judge for hallucination detection, and send only grounded answers to helpfulness or style assessment.

    MLflow’s built-in RAG judges cover retrieval relevance, groundedness, and context sufficiency. That separation helps you locate whether a failure began in retrieval or answer generation.

    Monitor the Judge in Production

    Offline benchmarks catch known failures. Automated evaluation needs production monitoring to catch the requests, document changes, and tool behaviors your original dataset missed.

    Sample traces and keep evaluator inputs

    Score a representative sample of live traffic, then oversample high-risk routes. Include failed tool calls, low retrieval confidence, long sessions, a multi-turn conversation, and answers that users flagged or regenerated.

    For each evaluation, store the original request, candidate output, retrieved passages, evaluator prompt version, judge model, generation model, temperature, top-p, system prompt, thresholds, chunk size, and overlap. A temperature change is a new experiment, not a minor implementation detail.

    MLflow’s end-to-end RAG evaluation cookbook shows why retrieval and generation need separate evaluation paths.

    Watch distributions, not only averages

    A rising average metric score can hide a growing failure rate in one important segment. Break results down by language, route, customer tier, content source, tool path, and request type.

    Set alerts for score shifts, pass-rate drops, rising review decisions, and disagreement between judges. Run regression testing against a small human-labeled evaluation dataset after you change the judge model, rubric, retrieval pipeline, or output schema.

    Keep a rollback path for evaluator prompts. Otherwise, you won’t know whether a score change came from your application or the evaluator itself.

    Applying the Method to AI Tool Content

    AI content sites often publish pages that look easy to assess but contain factual traps. An LLM-as-a-Judge can help, but its rubric should reflect whether the page is a directory, product comparison, or generated article.

    Evaluate directories for verifiable claims

    For general AI tool directories, check whether entries are distinct, accurately categorized, and supported by current product information. In reference-based evaluation, dated product pages, pricing, feature lists, and source material can verify those claims.

    A complete AI tools list should not call inactive products current, and a comprehensive AI list should not claim a feature without evidence.

    You can use deterministic checks for duplicate domains, missing prices, empty categories, and broken links. Then use the model to assess whether the category description matches the product.

    That applies to a free AI tools list, a premium AI software list, and pages covering new AI tools for 2026. Claims about the best AI tools for 2026 or top-rated AI software need dated evidence and a stated selection method.

    Grade writing tools on the requested job

    An AI writing tools list needs task-specific evaluation. The criteria for best AI copywriter tools differ from those for AI blog post generators, AI grammar checkers, or AI essay writing tools.

    For example, score a blog generator on factual grounding, outline coherence, source use, and adherence to the intended audience. Score a grammar tool review on error detection, correction quality, and whether it distinguishes style preference from grammatical error. Use few-shot prompting with boundary examples to show what passes and fails. Don’t let those examples reward a particular writing style.

    A generic “helpfulness” judge will blur those differences. A narrow rubric keeps the evaluation tied to what readers need.

    Frequently Asked Questions

    How does LLM-as-a-judge compare with BLEU?

    BLEU measures word overlap with a reference. It can help with narrow tasks that expect specific phrasing, but it often misses whether a response is helpful, grounded, or appropriate.

    An LLM judge can assess those broader qualities. However, it can also be inconsistent or biased, so use it alongside deterministic checks and human calibration.

    When should you use few-shot prompting in an evaluation prompt?

    Use it only when the rubric is difficult to interpret. Add two to four boundary examples that clarify what should pass or fail.

    Examples can also create style or verbosity bias. Check that the judge evaluates quality rather than copying an example’s presentation.

    Should you use the same model to generate and judge?

    You can, but you should test for self-preference. A judge may favor familiar wording, reasoning patterns, or formatting.

    Using a different capable model or a mixed evaluation panel can expose that issue. Either way, compare the judge against your human-labeled calibration set before relying on it.

    How often should human reviewers check outputs?

    Review cases at the release stage, after any major evaluator change, and on a recurring sample of production traffic. Increase review for safety-sensitive workflows and low-confidence decisions.

    Human reviewers should also inspect examples where judges disagree. Those cases often reveal rubric gaps or evaluation criteria that combine too many concepts.

    Make Automated Evaluation Earn Your Trust

    An LLM-as-a-Judge evaluation methodology works when you define evidence, score anchors, and failure categories before scoring outputs. The model should support your quality standard, not invent it.

    Maintain an evaluation dataset for calibration and change checks to preserve model alignment with your team’s quality standard. Use deterministic checks for facts your system can prove. Then use human evaluation for the subjective decisions that remain.

  • Prompt Unit Testing for Safer LLM Releases

    Prompt Unit Testing for Safer LLM Releases

    A polished demo can hide a broken generative AI application built with large language models. One prompt change may produce malformed JSON, unsupported product claims, or a refusal that blocks a paying customer.

    Prompt unit testing gives you a repeatable way to catch failures before release. Prompt testing exposes malformed output, unsupported claims, and unsafe refusals before release. You define what must remain true, test known inputs, measure variable outputs, and block deployments that fall below your quality bar.

    The work starts when you treat each prompt as a versioned prompt engineering artifact with a clear contract.

    Key Takeaways

    • Treat every prompt as a versioned artifact with a clear behavioral contract covering facts, safety, format, tool use, and user intent.
    • Build deterministic fixtures around happy paths, boundaries, missing context, tool failures, and adversarial inputs instead of testing ideal examples alone.
    • Combine structured output validation and exact assertions with semantic rubrics for requirements where wording can vary.
    • Measure repeated executions with risk-based thresholds, then use CI gates to block schema violations, unsafe behavior, regressions, and unacceptable quality declines.
    • Use production incidents and failure evidence to expand the suite, while keeping prompt tests distinct from ordinary code coverage and static analysis.

    What prompt unit testing actually tests

    Prompt testing evaluates a behavioral contract, not identical prose from a stochastic model. Large language models can vary wording, ordering, or detail across runs. Yet applications built with generative AI still need stable behavior around facts, safety, format, tool use, and user intent.

    Effective prompt unit tests separate fixed requirements from acceptable variation. That distinction prevents brittle tests while still holding the model accountable.

    Separate prompt logic failures from model variability

    Prompt testing should separate prompt logic failures from model variability.

    A prompt logic failure happens when the instruction or surrounding application design is wrong. For example, a support bot may expose an internal policy because its system prompt never prohibits disclosure. A product assistant may invent an unsupported price when retrieval context is missing.

    Model variability occurs when several outputs are acceptable. One response might say “cancel your subscription,” while another says “end your plan.” These valid paraphrases can pass if they provide the correct action and don’t make unsupported claims.

    Test logic failures with strict checks, including refusal behavior when policy requires it. Test variable language with semantic checks, scoring thresholds, and repeated runs.

    A passing response is not merely fluent. It must satisfy the behavior your product promises.

    Test the whole prompt contract

    Prompt engineering defines instructions and constraints, including input validation, output validation, prohibited behavior, tool access, and fallback rules. A travel-planning agent, for instance, may require valid JSON, cite only supplied inventory, ask a clarifying question when dates are absent, and never claim a booking succeeded.

    Keep this contract and its test suites close to the prompt in your repository. Version them together so model behavior stays reviewable and release decisions become more reliable. Changing prompt text without updating its test cases creates a gap that release reviews won’t catch, weakening software reliability.

    Build fixtures that expose real failure modes

    Fixtures are controlled inputs that make failures repeatable. Each fixture should capture the user message, relevant retrieved documents, tool responses, tenant settings, and conversation history that affects the result. These test cases keep prompt testing grounded in conditions your application can reproduce.

    Don’t build a suite from ideal examples alone. A happy path test proves that the app can work, but it says little about behavior under pressure. Over time, realistic fixtures expand test suites around real failure modes.

    Freeze the context around each test

    Use a stable fixture for retrieval-augmented generation. Prompt testing should include the exact policy text when a test asks, “Can I return an item after 45 days?” Include the exact policy text that answers it. Don’t call a live knowledge base during a unit test, because document updates can turn a useful failure into noise.

    For tool-using agents, prompt testing also requires realistic stub responses. A payment API fixture might return a successful charge, an expired card, a timeout, or a 429 rate-limit response. These stubs let you test user-facing language without charging a card or depending on a vendor outage. They also make error handling deterministic for timeouts, rate limits, and rejected access.

    Traditional code follows the same principle. In Jest, pytest, or JUnit, use a testing framework to isolate logic with mock objects at external boundaries.

    Cover the success case, boundaries, and errors

    Each important prompt behavior needs tests that pull in different directions. For prompt testing, use a compact matrix that maps each scenario to a deterministic assertion or expected safe behavior. Boundary, missing-context, and adversarial inputs are edge cases worth pinning down, and these edge cases keep test cases readable and repeatable:

    Test scenarioFixed conditionUseful assertion
    Happy pathA valid request gets a complete answerRequired fields and correct action
    Boundary inputThe request is empty, oversized, or ambiguous, triggering input validationClarifying question or safe limit
    Missing contextRetrieval returns no supporting sourceAdmits uncertainty without inventing facts
    Tool failureA dependency times out, returns a 429, or rejects accessExplains next step without exposing internals
    Adversarial inputA user attempts instruction overrideIgnores the attack and follows system rules

    Use production incidents, support tickets, and failed sales conversations to add fixtures. Turn those scenarios into deterministic test cases for automated testing. They carry more value than another cheerful demo question.

    Code coverage metrics complement behavioral fixture coverage, but they don’t replace it.

    Use structured outputs and semantic assertions together

    Free-form prose is difficult to test. For reliable prompt testing, request structured output with a schema before your code acts on the response.

    For example, a content workflow might require title, summary, audience, claims, and sources. Your application can reject a response that omits a required field or returns an invalid type. Schema validation turns many LLM defects into ordinary software failures. A clear output schema strengthens prompt engineering, but it isn’t a substitute for measuring model quality.

    Make objective requirements machine-checkable

    Use prompt testing to assert exact values when the product requires them. For test cases with exact requirements, assert the expected value directly. Use input validation for JSON parsing, required fields, enum membership, numeric ranges, prohibited phrases, supported language codes, and tool-call arguments.

    Don’t assert the entire response string unless every word matters. A full-string match breaks after harmless rephrasing and encourages teams to ignore failures. Instead, test a short list of product requirements. High code coverage in the evaluation harness doesn’t prove semantic coverage of model behavior.

    For LLM output validation, Promptfoo’s assertion and metrics documentation describes deterministic checks alongside similarity and model-graded assertions. promptfoo supports deterministic, similarity, and model-graded assertions, so that mix fits most production suites.

    Grade meaning when wording can vary

    Use prompt testing with a semantic rubric for claims such as “the response answers the question,” “the advice matches the supplied policy,” or “the tone is professional without being evasive.” Give the grader a narrow rubric, the expected context, and an explicit passing score.

    A useful rubric for a medical-adjacent wellness app might require the answer to avoid diagnosis, recommend professional care for urgent symptoms, and cite only approved material. The grader must reward policy compliance, not merely fluent prose.

    Set thresholds for prompt testing based on observed baseline results. If a rubric score ranges from zero to one, a 0.8 threshold can work for high-risk factual tasks. Run a calibration set first with representative test cases. Review borderline failures manually, then adjust the rubric or threshold with evidence.

    Prompt templates can also improve code unit tests

    LLMs can draft tests for ordinary application code, but generated code needs the same discipline as generated prose. Ordinary unit testing checks application behavior, while prompt testing evaluates an LLM response. Models may guess private methods, invent library APIs, or assert against implementation details.

    Use prompt engineering for a compact, factual brief covering the target file, public interface, framework version, and testing framework (Jest, python pytest, or JUnit tests). Also specify the assertion library, existing conventions, allowed dependencies, and TypeScript code details. Good prompt engineering makes framework-specific conventions explicit, not inferred, especially for JUnit tests; state that production code must not change.

    Ask for an Arrange-Act-Assert test shape

    In prompt testing, require each generated test to follow Arrange-Act-Assert. The arrangement prepares inputs and mocks. The action calls one public behavior. The assertion verifies observable output or side effects.

    This pattern makes review faster and helps reveal gaps in branch and line code coverage. It also reduces test logic that accidentally reproduces the production algorithm. If a test contains loops, conditionals, several unrelated expectations, or assertion roulette, split it before accepting the output. Treat over-mocked or assertion-heavy tests as test smells; readable fixtures and clear failure messages support code maintainability.

    Ask the model to generate a test plan before code when a function has many branches. Chain of thought may help organize cases, but hidden reasoning isn’t test evidence. Judge the compiled test and its assertions instead, and don’t treat code coverage as proof of meaningful assertions.

    Mock boundaries, not the behavior you need to prove

    Use mock objects for databases, HTTP clients, clocks, queues, file systems, and third-party SDKs. They should represent external boundaries, not the function or behavior being proven. In prompt testing, keep the unit’s business rules real; mocking the function under test or every internal collaborator can let the suite pass while the feature fails.

    Code compilation is the first gate for AI-generated code. Next, run formatting, linting, type checking, and static analysis as separate gates. During prompt testing, review static analysis results and rerun static analysis after meaningful changes.

    Measure reliability across repeated executions

    One successful run proves little when a model samples tokens probabilistically. For generative AI, prompt testing needs a repeat policy when outputs may change, especially for agent planning, model-graded answers, and creative copy.

    Run high-value test cases several times at the same model settings. Track pass rate, median score, lowest score, latency, token use, and error count. A response that passes four times out of five is a release risk when the task handles payments, permissions, or regulated claims.

    Set release thresholds that match risk

    Risk-based prompt testing should give each test tier an owner and a clear gate. These thresholds support software reliability without treating every variation as a release blocker.

    Schema violations, data leaks, successful prompt injection, and unsafe tool calls should fail immediately. Less severe style variations can use a pass-rate threshold.

    For example, you might require:

    • Every critical security and schema test to pass.
    • At least 95 percent success across repeated core-task fixtures.
    • A minimum semantic score for policy-grounded answers.
    • No material decline in latency, cost, or refusal quality against the previous release.

    Promptfoo supports repeated evaluations and delays. Promptfoo also supports weighted assertions and per-assertion thresholds. Use Promptfoo’s retry controls for transient provider transport errors as part of error handling. Those controls let you distinguish an API hiccup from a repeatable regression.

    Gate releases in continuous integration

    Run small pull-request test suites as smoke tests for prompt testing, covering the highest-risk contracts quickly. Alongside automated testing, run linting, type checking, compilation, and static analysis as separate gates. Run broader regression test suites for prompt testing before a production deployment or on a scheduled build.

    Export prompt testing results through Promptfoo into your CI artifacts. Reviewers should be able to inspect failed inputs, test cases, prompt versions, model identifiers, scores, and error messages. Include application or harness code coverage in those reports. Still, code coverage can’t replace behavioral assertions, and static analysis failures should be reported separately. Promptfoo’s CI result handling shouldn’t silently retry a failed quality assertion. Retries belong to transport and provider errors, not to bad answers.

    When prompt testing fails, classify the cause. The failure may come from changed instructions, weak retrieval, a model update, a broken parser, an unavailable tool, or an overly rigid assertion. That classification tells you what to fix.

    Test recommendation and content applications honestly

    Prompt testing matters beyond chatbots. In generative AI products, a directory or recommendation engine can mislead users with stale rankings, invented pricing, or category confusion.

    A person searching for general AI tool directories, a complete AI tools list, the best AI tools 2026, or top-rated AI software expects current, attributable recommendations. Use test cases for directory entries, pricing, rankings, and writing tools. They should require source-backed facts, flag stale records, and show uncertainty when records are incomplete.

    Create query fixtures for content and writing AI

    Recommendation prompts should handle natural search requests without collapsing different needs into one generic answer. Prompt testing should verify that each fixture preserves user intent.

    Prompt engineering should state selection criteria and distinguish user intent. Prompt testing should cover an AI tool directory, a comprehensive AI list, a free AI tools list, a premium AI software list, and new AI tools 2026.

    Test content and writing AI queries separately. Prompt testing should apply different comparison criteria to an AI writing tools list, best AI copywriter tools, AI blog post generators, AI grammar checkers, and AI essay writing tools. Good prompt engineering keeps those needs distinct. Grammar tools may need language support and privacy details, while copywriters need brand-control and workflow criteria.

    Your assertions should check that the response states selection criteria and cites sources. They should also flag fabricated ratings, distinguish free tiers from paid plans, and avoid presenting sponsored placement as an objective ranking.

    Choose evaluation tools based on the workflow

    A CLI-first workflow, such as Promptfoo, suits teams that want YAML or file-based test suites in source control and CI. Prompt testing may favor a hosted evaluation platform when teams need collaborative annotation, production traces, and dataset management.

    Tool selection should follow your failure modes. Prompt testing should compare workflow fit, assertion depth, and observability, not just brand familiarity. Promptfoo can represent the local, configuration-led side of that choice, as shown in the Promptfoo and Braintrust comparison.

    If you’re also comparing a testing framework, Promptfoo can be evaluated alongside DeepEval; this Promptfoo versus DeepEval overview maps assertion and grading options. No tool replaces a well-defined contract. Start with a small suite tied to costly failures, then expand it with production evidence.

    Frequently Asked Questions

    What is prompt unit testing?

    Prompt unit testing evaluates whether an LLM application consistently satisfies a defined behavioral contract. It checks requirements such as valid structure, grounded claims, safe refusals, correct tool use, and appropriate handling of user intent.

    How should prompt tests handle variable model responses?

    Tests should use exact assertions for fixed requirements and semantic checks for acceptable variations in wording. Repeated runs, scoring thresholds, and narrow evaluation rubrics help distinguish harmless variability from meaningful regressions.

    What should a prompt testing fixture contain?

    A fixture should include the user input, retrieved documents, tool responses, tenant settings, and conversation history that affect the result. Stable fixtures and stubbed external dependencies make failures repeatable without relying on live services.

    How do prompt tests fit into continuous integration?

    Run a small set of high-risk smoke tests on pull requests and broader regression suites before deployment or on scheduled builds. CI reports should include prompt versions, model identifiers, failed inputs, scores, and error messages so reviewers can classify and fix failures.

    Can code coverage replace prompt testing?

    No. Code coverage shows which application paths executed, while prompt testing evaluates whether model behavior meets product and safety requirements. Both are useful, but neither replaces the other.

    Reliable releases come from explicit evidence

    Prompt testing turns vague impressions into observable evidence, making generative ai releases easier to judge. You can validate schemas, isolate dependencies, assess meaning, measure variance, and detect regressions before users find them.

    The strongest suite tests the promises your application makes, especially when an answer from large language models looks convincing but is wrong. Software reliability comes from clear contracts, deterministic checks, repeated evaluation, and automated testing, not a successful demo.

  • Prompt Compression for Long-Context LLMs

    Prompt Compression for Long-Context LLMs

    A large context window increases capacity, but it doesn’t perform context compression or reduce token usage. Long prompts raise input costs, slow first-token response time, and can bury the evidence your model needs most.

    Prompt compression reduces the tokens sent to large language models while retaining the facts, instructions, and context that affect the result. If you run retrieval, support agents, research workflows, or content systems, disciplined compression can improve both budget control and answer quality.

    The work begins by ensuring the input prompt contains only decision-relevant material, with selective context chosen for the task.

    Key Takeaways

    • Prompt compression reduces input tokens, cost, and latency while preserving the instructions, facts, and evidence that affect the result.
    • Start with retrieval, deduplication, and deterministic cleanup before applying model-based compression or token-level methods such as LLMLingua.
    • Protect system instructions, tool schemas, numbers, dates, names, IDs, negations, legal language, and other high-risk fields through explicit retention policies and validation checks.
    • Compress retrieved context after retrieval, preserve evidence boundaries and citations, and manage long conversations with tiered memory and protected durable facts.
    • Measure end-task accuracy, fidelity, latency, cost, and fallback behavior alongside token reduction; the lowest token budget is useful only when quality remains above the required threshold.

    What prompt compression changes in an LLM request

    For large language models, prompt compression removes low-value material before the primary model processes it. The goal is not attractive prose. The goal is to preserve the information needed for the next task with fewer tokens. It should preserve task instructions and answer-bearing evidence, not attempt to reproduce hidden chain-of-thought reasoning.

    A customer support agent may receive a 40-message thread. Much of it could be greetings, repeated status updates, or resolved issues. The final model needs the customer’s identity, active issue, promised action, deadlines, product details, and current instruction hierarchy.

    These approaches solve different parts of the request:

    • Summarization interprets content and creates a shorter narrative representation. It may reorganize details instead of preserving every source phrase.
    • Retrieval selects candidate evidence from a larger corpus. It doesn’t necessarily shorten or rewrite the passages it finds.
    • More available input capacity lets a model accept more material, but doesn’t reduce token billing or prevent attention dilution.
    • Compression prunes, rewrites, or encodes supplied context before inference.

    You’ll often combine all four. Retrieval selects candidate evidence, compression reduces it, and summarization preserves older conversation as a narrative in the assembled input prompt.

    Why long prompts hurt cost, latency, and accuracy

    Every input token consumes computation in large language models, adding to computational cost. Prompt compression can reduce input size, while long prompts increase inference latency before generation begins.

    This matters most when your system makes many similar requests. A single 10,000-token prompt may be acceptable for a research task. A customer-facing agent handling thousands of requests per day needs a tighter budget. Compression can improve response latency and time to first token when its overhead is justified.

    Attention is not a filing cabinet

    More context can reduce accuracy when important passages compete with repetitive or weakly related text. Models operating near their context window also show position effects, where evidence in some locations receives less attention than evidence near the beginning or end.

    The LongLLMLingua ACL paper identifies cost, performance reduction, and position bias as key long-context challenges. Removing irrelevant material can therefore improve an answer even when the original prompt fits inside the model’s context window.

    Token savings are not the only metric

    A 90% reduction looks impressive until the compressor drops “not,” changes “within 24 hours” to “soon,” or removes a contract exception. Measure end-task success, not token count alone.

    A compression ratio is useful only when the compressed prompt preserves the details that would change the model’s decision or answer.

    Track token usage separately from end-task success. Also measure compressor latency, primary-model latency, input cost, answer quality, and human escalation rate. One score cannot capture the full trade-off.

    Identify what must survive before you compress

    You need a retention policy before choosing a model or writing a prompt for prompt compression. This policy defines semantic retention, meaning which information must survive, not just which words remain.

    Start by separating context into four classes. System instructions and tool schemas usually need exact preservation. User constraints, legal language, numerical data, dates, names, IDs, and negations also deserve protected handling. Supporting evidence can often be shortened. Boilerplate and duplicates can usually disappear.

    Protect high-risk details

    Numbers carry more meaning than their length suggests. “Up to 10 users” differs from “10 users.” A $5,000 monthly cap differs from a $5,000 annual cap. Version numbers, ISO dates, units, percentages, and currency values should pass through validation after compression.

    You should also preserve instruction priority. A compressor must never let retrieved text override your system message. Keep stable system instructions and tool schemas outside the compressor where possible. Preserve required instructions and verifiable evidence, rather than attempting to retain private chain-of-thought text. Compress only retrieved chunks and old conversation turns.

    Use a schema when the task allows it

    Structured extraction offers a safer option than free-form shortening when the task allows it. For a claims workflow, extract fields such as policy number, incident date, coverage status, amount, and missing documents. Send the model a compact JSON-like representation or concise labeled fields.

    This reduces ambiguity and makes automated checks practical. If the source contains a deadline, your test can verify that the same date appears in the compressed output.

    Hard prompt compression techniques that work in practice

    A hard prompt output is a shorter text made of discrete tokens that remains readable, editable, and auditable. You can inspect it, log it, test it, and show it to an auditor. That visibility makes this approach the usual starting point for production applications.

    Remove duplication and formatting noise

    Exact duplicate chunks, repeated navigation text, verbose metadata, and template language add tokens without adding evidence. Remove them upstream as token-level optimization, before a language-aware compressor runs.

    You can also normalize document formats. Convert tables into compact rows when their column meaning remains clear. Collapse repeated headings. Strip URLs that have no role in the answer. Preserve source IDs separately if your application needs citations.

    Extract evidence rather than shortening everything

    Extractive compression keeps the most relevant sentences, entities, clauses, or spans. For question answering, rank passages against the user query, then retain sentences with direct support.

    Semantic rewriting can compress further, but it introduces a greater risk of altered meaning. Use it for low-risk history and descriptive text. Avoid it for specifications, financial terms, policy language, or code where punctuation may matter.

    A simple five-step workflow separates cleanup, retrieval, extraction, and final prompt construction:

    1. Deduplicate and remove known boilerplate as an upstream cleanup step.
    2. Retrieve a limited set of candidate passages with metadata.
    3. Use query-aware compression when ranking passages against the user query, then extract answer-bearing spans.
    4. Compress only the remaining context under a fixed token budget, then construct the final prompt with its instructions and metadata.
    5. Validate protected fields before sending the input prompt to the primary model.

    This sequence keeps compression focused on evidence that survived retrieval and extraction. It prevents a costly compressor from spending time on material you should have discarded earlier.

    LLMLingua and token-level prompt compression

    Microsoft’s LLMLingua family is a widely used approach to prompt compression. The original method uses a smaller language model and a budget controller. That controller identifies lower-value tokens before the target LLM receives the prompt and helps enforce token limits.

    The LLMLingua repository documents reported compression of up to 20x in evaluated settings. These levels depend on the dataset, task, and evaluation setup. Treat them as research and implementation references, not promises for every workload.

    Choose the variant for the workload

    Original LLMLingua applies coarse-to-fine compression and can work well when you need controllable token budgets. It suits demonstrations, documents, and instructions, but protect instruction text that can’t tolerate alteration.

    LLMLingua-2 uses GPT-4 data distillation to train a BERT-level token classifier. Microsoft describes it as task-agnostic and focused on efficiency and faithfulness in its project overview. Its lightweight classifier supports controlled token-level optimization and can make compression faster than relying on a generative helper model.

    LongLLMLingua targets long-context cases and incorporates document ranking concerns. Consider it when RAG prompts contain many retrieved passages and evidence placement affects downstream task performance.

    Use this comparison checklist to verify each tool against your workload.

    Comparison areaPractical checkRelated guidance
    Supported inputsReview PCToolkit’s documented input types and supported prompt components.Compare them with the classifier-oriented workflow of LLMLingua-2.
    Budget controlsCheck PCToolkit’s documented budget controls before setting a target.Coarse-to-fine methods suit workloads requiring controlled budgets.
    Output inspectionInspect PCToolkit outputs for lost instructions, numbers, or evidence.Preserve content that cannot tolerate alteration.
    EvaluationUse PCToolkit’s documented evaluation options with representative tasks.Compare retrieved-passage workloads with LongLLMLingua.

    If it appears in your evaluation, treat 500xCompressor as a separate implementation or benchmark reference. Verify its documentation and claims before relying on it.

    Account for compressor overhead

    A compressor adds a model call or inference step. For small prompts, its added inference latency can exceed the primary model’s response latency and erase savings. Benchmark the whole request path, including retrieval, compression, primary inference, and validation, to measure computational cost.

    Microsoft’s AutoGen LLMLingua example is a useful reference for placing compression in a long-context pipeline. Run it against your own traffic shape before setting a global token target.

    Hard and soft prompt compression solve different problems

    Hard methods return readable, editable text. You can inspect which terms remain and tune rules for protected content. They also work with hosted model APIs because they operate before the primary request.

    A soft prompt encodes information as learned continuous vectors or special embeddings. These representations aren’t human-readable text. In a trained system, they can pack task-relevant patterns into a smaller representation than natural language allows.

    When soft prompts make sense

    Soft methods fit stable, high-volume tasks where you control the model integration and can train or tune an encoder. A soft prompt may capture recurring workflow context without repeatedly sending extensive natural-language instructions.

    However, a soft prompt isn’t a universal replacement for retrieved facts, context-window expansion, or ordinary prompt shortening. It isn’t a general-purpose container for fresh chain-of-thought or newly retrieved evidence. If today’s query depends on a new policy document or product release, you still need a way to represent that evidence faithfully.

    The trade-off is operational. Hard compression is portable and auditable. Soft compression can be compact, but requires compatible infrastructure, training data, evaluation, and version control. You should retain a textual fallback for debugging and regulated decisions.

    Compress RAG context after retrieval, not before

    Retrieval-augmented generation (RAG) has two separate token problems, so prompt compression should address them at the right stage. First, broad retrieval can select too many chunks. Second, relevant chunks can still contain too much surrounding text.

    Compressing the entire knowledge base before indexing can erase retrieval terms and weaken recall. Keep source documents intact or lightly normalized for indexing. Then use query-aware selection followed by query-aware compression after retrieval.

    Preserve evidence boundaries and citations

    Passage boundaries matter for context compression. If a compressor merges statements from two sources, the model may produce a confident claim with an unclear citation trail. Keep document ID, chunk ID, title, and original character offsets alongside each retained span.

    For factual answers in retrieval-augmented generation, ask the model to cite source IDs from the compressed evidence. Your evaluator can then compare cited claims with the original passages. If compression drops support for a claim, the model should abstain or request more retrieval.

    A directory search example

    A general AI tool directory can create an unusually noisy RAG corpus. A complete AI tools list may contain duplicate descriptions, affiliate copy, old release notes, pricing fragments, and similar category pages.

    Phrases such as best AI tools 2026, top-rated AI software, and new AI tools 2026 are noisy retrieval metadata, not SEO terms to repeat in compressed evidence. Someone searching for these terms expects current product facts. Filter by update date and product identity first. Then compression can retain pricing, capabilities, limits, and source dates without carrying every promotional sentence.

    For a Content & Writing AI category, an AI writing tools list may overlap with best AI copywriter tools, AI blog post generators, AI grammar checkers, and AI essay writing tools. Normalize these labels into metadata. A comprehensive AI list can still separate a free AI tools list from a premium AI software list without repeating the same product copy in every retrieved chunk.

    Manage long conversations with tiered memory

    Conversation history grows one turn at a time, yet older messages don’t all have equal value. Recent turns often need verbatim treatment because they establish the immediate task. Earlier turns usually need context compression, often through conversation summarization, plus a small set of verified facts.

    Store durable facts separately from the conversational transcript. Examples include account ID, product plan, current incident status, unresolved requests, user preferences, and promises made by the agent. Treat context compression as summary memory, and update those protected facts only after validation.

    Set thresholds and reset rules

    Use prompt compression at a planned threshold for older turns, before the context window is nearly full. Account for token limits by reserving space for the next user message, tool outputs, and the model’s expected answer. A system that compresses only after a context-limit failure is already too late.

    IBM’s watsonx Orchestrate context guidance describes compressing older messages while retaining recent context. This system-level approach helps preserve conversation continuity, but its summaries shouldn’t replace a protected facts store.

    For a production deployment, record these controls and verify their implementation against current documentation:

    ControlExample check
    ThresholdFor watsonx Orchestrate, document and test the point that starts compression before budget pressure.
    Maximum tokensFor watsonx Orchestrate, record the input and output budgets used by the deployment.
    Compression instructionsFor watsonx Orchestrate, version instructions that identify facts, tasks, and recent turns to preserve.
    PermissionsFor watsonx Orchestrate, restrict changes to memory and compression settings to approved operators.
    Recent-message retentionFor watsonx Orchestrate, define the number of recent messages retained verbatim and test it.
    Durable factsFor watsonx Orchestrate, map validated facts to a protected store or approved state mechanism.
    Reset behaviorFor watsonx Orchestrate, document when memory resets after task completion or session closure.
    FallbackIf compression fails, retain recent history and stop safely rather than silently dropping facts.

    After a major task closes, create a final verified state record. Then remove detailed history unless your retention policy requires it. For production conversation systems, carrying old dialogue into unrelated work creates token cost and privacy risk in enterprise workflows.

    Test fidelity before you lower the token budget

    Evaluate prompt compression by testing downstream behavior, not token savings alone. Overcompression risks can produce fluent answers that miss deadlines, confuse entities, or ignore exceptions.

    Build a fixed evaluation set from real, de-identified cases. Include long documents, contradictory evidence, repeated facts, retrieval noise, tables, user corrections, tool instructions, and multilingual text if your product supports it.

    Compare full context with compressed context

    Run the same task with uncompressed and compressed prompts. Score answer accuracy, citation precision, tool-call correctness, instruction adherence, and protected-field fidelity, not hidden reasoning. Compare the compression ratio with end-task accuracy, latency, and cost.

    MeasureWhat you should check
    Token reductionInput tokens before and after compression
    End-task accuracyWhether the final answer or action remains correct
    Fidelity checksSemantic retention for dates, amounts, names, negations, IDs, and constraints
    LatencyCompressor time plus time to first token and total response
    CostCompressor compute and primary-model input savings

    The right setting is the lowest token budget that meets your quality threshold. Different tasks will produce different answers. A support classifier may tolerate aggressive reduction, while legal review may need near-verbatim evidence.

    Add guardrails around instructions and numbers

    Prompt injection can arrive through retrieved documents, emails, web pages, and uploaded files. Prompt compression reduces length, but it doesn’t make untrusted instructions safe. A shorter malicious instruction remains malicious.

    Keep system and developer instructions outside untrusted context. Label retrieved text as reference material, and don’t let untrusted documents instruct a compressor to reveal, preserve, or follow hidden chain-of-thought content. Require tool calls to follow structured schemas and server-side permission checks, rather than trusting instructions found in a document.

    Validate what compression must not change

    Create deterministic checks for fields that matter. Compare all dates, amounts, units, names, model numbers, threshold values, and negation terms against the source. If validation fails, retry with a higher token budget or pass the original span.

    For sensitive workflows, retain the original source and compressed form in request logs with appropriate access controls. When an evaluator finds a bad answer, you need to know whether retrieval, compression, prompting, or model generation introduced the error.

    Use compression as part of an enterprise workflow

    Enterprise deployment needs more than prompt compression. Enterprise workflows also need ownership of source quality, logging, permissions, evaluation, fallback behavior, and a clear cost model.

    Don’t treat an orchestration summary as equivalent to token-level pruning. Context compression at the orchestration layer preserves a working conversation summary, while a hard prompt cleanup changes text directly and remains portable and inspectable. LLMLingua-style pruning targets useful prompt information under a direct token budget, so use both approaches only with separate tests.

    Use a policy matrix to turn those distinctions into operational controls.

    Implementation matrix: IBM watsonx Orchestrate

    ConcernImplementation policy
    Compression thresholdConfigure a compression threshold in watsonx Orchestrate based on prompt size and workflow risk.
    Maximum tokensSet maximum tokens in watsonx Orchestrate to protect latency and cost budgets.
    Compression instructionsVersion compression instructions in watsonx Orchestrate with the workflow prompt.
    Permission to compressRequire explicit permission in watsonx Orchestrate before compressing protected context.
    Recent-context handlingPreserve recent turns when watsonx Orchestrate compacts an active conversation.
    Fallback behaviorDefine a fallback in watsonx Orchestrate for failed, low-confidence, or over-compressed results.
    LoggingRecord compression decisions and token counts from watsonx Orchestrate for later review.
    Request routingRoute requests through watsonx Orchestrate according to size, risk, and retrieval type.
    Access controlLimit policy changes in watsonx Orchestrate to approved workflow owners.
    EvaluationCompare compressed and full prompts through evaluations connected to watsonx Orchestrate.
    Policy ownershipAssign an accountable owner for watsonx Orchestrate compression policies and revisions.
    Short support chatsConfigure watsonx Orchestrate to skip compression for short, low-risk support chats.
    Extended agent workflowsApply a larger context budget and explicit summaries in watsonx Orchestrate for extended agent workflows.

    A mature flow routes requests by size and risk. In enterprise workflows, short prompts skip compression, medium prompts receive deterministic cleanup, and long, low-risk RAG contexts receive model-based compression. High-risk cases keep protected evidence verbatim and use a larger budget.

    A practical rollout plan for prompt compression

    Start with observability rather than aggressive reduction. Log token usage by prompt component, including system instructions, user content, conversation history, retrieved passages, tools, and examples. This shows where the waste actually sits.

    Next, remove repeated boilerplate and limit retrieval. Those changes are easy to verify and often produce the first meaningful savings. Add extractive compression or LLMLingua only after you have an evaluation baseline.

    Roll out by task class, starting with internal search, document triage, or low-risk content assistance in enterprise workflows. Keep an uncompressed fallback while validating prompt compression, and sample requests for side-by-side review. Tighten budgets gradually with token-level optimization, because a threshold that works for one document set may fail on another.

    Use a neutral tool-selection and product-policy checklist during each pilot:

    • Pilot selection: Include PCToolkit in comparisons against task risk, data, and evaluation needs.
    • Observability: Record component-level changes when reviewing PCToolkit.
    • Fallback: Document the uncompressed path alongside PCToolkit.
    • Regression testing: Include PCToolkit in the same evaluation set after budget changes.
    • Configuration: Review watsonx Orchestrate settings against approved workflows.
    • Permissions: Verify watsonx Orchestrate permissions before the pilot.
    • Thresholds: Record watsonx Orchestrate thresholds and their owners.
    • Monitoring: Schedule post-change monitoring for watsonx Orchestrate.

    You should also revisit context compression after model, prompt, or retrieval changes. A better retriever can reduce the need for aggressive pruning. A new system prompt can change which tokens carry instruction meaning.

    Frequently Asked Questions

    What is prompt compression?

    Prompt compression reduces the number of tokens sent to a large language model while retaining the information needed for the task. It can remove duplication, extract relevant evidence, rewrite lower-risk context, or encode information into a compact representation.

    How is prompt compression different from summarization and retrieval?

    Retrieval selects candidate evidence, while summarization creates a shorter narrative representation of content. Compression focuses on reducing the supplied context before inference, and it is often combined with retrieval and summarization in the same workflow.

    What information should not be compressed aggressively?

    System instructions, tool schemas, legal language, numbers, dates, names, IDs, units, thresholds, and negations require protected handling. Validate these fields against the original source and retain the original span when the compressed version changes or loses important details.

    Should RAG context be compressed before or after retrieval?

    Compress retrieved context after retrieval and query-aware selection. Compressing the full knowledge base before indexing can remove useful retrieval terms and weaken recall, while post-retrieval compression reduces surrounding text without damaging the source corpus.

    How should prompt compression be evaluated?

    Compare full and compressed prompts on the same representative tasks. Measure end-task accuracy, citation precision, instruction adherence, protected-field fidelity, latency, cost, and token reduction rather than relying on compression ratio alone.

    Conclusion

    Long-context applications work better when you treat tokens as a budget, not free storage. Prompt compression reduces cost and latency, but it must preserve the evidence and instructions that determine a correct result.

    Start with retrieval quality, deterministic cleanup, and protected-field checks. Then test hard or soft compression against real tasks, using downstream accuracy as the deciding metric.

    The shortest prompt is useful only when prompt compression preserves the information your model needs to act.

  • Git-Based Prompt Versioning for Safer LLM Releases

    Git-Based Prompt Versioning for Safer LLM Releases

    A single prompt edit can change your product’s tone, accuracy, cost, and safety profile. Yet many teams still ship prompt changes from a code string, spreadsheet, or message thread with no reliable path back.

    prompt versioning turns prompts into release artifacts you can review, test, approve, deploy, and roll back. Git prompt management provides the foundation for review, approval, and recovery, but safe LLM releases need more than commit history.

    Once a prompt affects customers, treat it like an API change in the broader LLM release process.

    Key Takeaways

    • Treat prompts as release artifacts that require review, evaluation, approval, deployment, and rollback.
    • Version the full behavior contract, including models, parameters, retrieval settings, tools, schemas, data inputs, and prompt files.
    • Use immutable release identifiers and promote the exact evaluated commit through development, staging, and production.
    • Test candidate prompts with golden datasets, layered quality checks, regression comparisons, and human review.
    • Preserve evaluation evidence and production traces so teams can diagnose changes and restore a known-good release quickly.

    Why prompt versioning needs more than a Git commit

    Git records changes well and provides version control for your prompts. You can branch, compare diffs, merge work, and return to an earlier commit. If your team needs a refresher, Atlassian’s Git glossary covers the core terms behind that workflow.

    However, a prompt’s behavior doesn’t come from text alone. The same wording can produce different results when you change the model, temperature, retrieved documents, tool definitions, or output schema.

    Prompts have hidden dependencies

    A system prompt might ask for a concise product recommendation. Its production result also depends on the model provider, model release, token limit, retrieval settings, user inputs, and any tool calls available to the agent.

    If you version only this sentence, you can’t reproduce the release:

    Recommend three suitable tools and explain the trade-offs.

    You need the surrounding conditions that shaped the answer. Otherwise, version history tells you what text changed, but not what customers actually experienced.

    Non-deterministic behavior changes how you test

    Traditional code tests often expect an exact output. LLM applications require a wider view because non-deterministic behavior can produce different outputs that still meet your quality bar.

    Your prompt testing should cover factual grounding, formatting, safety, tool use, and task completion. Evaluation pipelines connect those checks to an LLM release process without requiring identical outputs. A prompt that sounds better in a playground may still fail when retrieval returns an outdated page or a user writes an ambiguous request.

    A branching code workflow moves through testing, approval, deployment, and rollback.

    A prompt release is reproducible only when you can identify the prompt, its runtime configuration, its data inputs, and the evaluation results that approved it.

    What to store beside every prompt

    Store prompts in Git as plain, reviewable files, then attach a machine-readable manifest that pins runtime choices. Together, these files support prompt versioning and prompt management by separating prompt content from deployment behavior. Git stores the associated configuration with each release, making the result reproducible.

    A small repository can store the system prompt and user message as prompt assets with reproducible variable substitutions:

    • prompts/product-advisor/system.md holds the system instructions.
    • prompts/product-advisor/user-template.md holds the variable-based user message.
    • prompts/product-advisor/config.yaml records the model, parameters, and schema.
    • evals/product-advisor/cases.jsonl stores test cases and expected criteria.
    • schemas/product-advisor-response.json defines the structured output.
    • tools/product-advisor.json records callable tools and their versions.

    Record the whole behavior contract

    Your config.yaml should capture the model name, provider, and model parameters, including temperature, top-p, token limits, timeout, and provider-supported seeds. Also record template variables, retrieval index version, embedding model, chunk size, reranker, and tool schema versions. The application should pin this full configuration in the production environment, rather than relying on defaults.

    This matters most in retrieval-augmented generation. RAG version control and experiment tracking should cover both the data path and the experiment record.

    Use immutable release identifiers

    Give each approved release a version identifier, such as a Git commit SHA, release tag, or equivalent stable reference like product-advisor-v1.4.0. Your application should load a pinned release reference for live workloads, never whatever happens to sit on the default branch.

    Tags make releases easier to read. For example, dev, staging, and production can point to approved commits. Move environment tags only through reviewed promotion steps, not through an unreviewed push.

    Structure Git-based prompt workflows for real collaboration

    Keep prompts near application code for engineers, while making them accessible to product and editorial teams. Markdown files make prompt versioning collaborative, so non-technical reviewers can comment on plain language without editing source code. That shared artifact speeds prompt iteration and refinement.

    For larger systems, split repositories by product boundary rather than forcing every prompt into one giant folder. An agent that qualifies leads should have a separate release history from a support assistant.

    Make prompt templates readable and constrained

    For prompt templates, use named variables with clear defaults, and document each variable beside the template. A template might accept audience, market, source_context, and brand_rules. Rendering it with representative values is more useful to reviewers than showing source text alone.

    Avoid inserting raw user content into privileged system instructions. Keep user input in its own message role, validate variables, and set length limits before interpolation.

    Let domain experts review the right artifact

    Product managers and marketers shouldn’t need to inspect application code to approve a tone change. Give them a pull request with the rendered template, representative inputs, model settings, and before-and-after outputs. Include the reason for the change as change documentation.

    Use a collaborative playground for rendered previews and experimentation, but keep the pull request as the formal approval record.

    This is also useful for editorial workflows. A classification change in a writing-tools directory can affect several category pages, so reviewers should inspect the rendered results before approval.

    Promote prompt changes through controlled environments

    An LLM release process needs more than ordinary application deployment gates. Standard build success isn’t enough when prompts can change behavior. This CI/CD overview for LLM applications supports adding prompt-specific checks to an evaluation pipeline.

    For environment deployment, use separate development, staging, and production references. Development is where you iterate quickly. Staging runs a candidate against realistic traffic patterns and representative data. Promote only a reviewed and evaluated commit to the production environment.

    Don’t make main equal production by default. A merged pull request may be correct in source control but still need human approval or staging evaluation.

    A practical change workflow

    Use a short, repeatable release path:

    1. Create a feature branch and edit the prompt, configuration, or tool definition.
    2. Run local tests against a small fixture set, then open a pull request with rendered examples.
    3. Merge the approved change and deploy its commit to staging.
    4. Run an automated evaluation against a representative dataset, then review sampled outputs from staging traces.
    5. Promote that exact commit to production with a release tag.
    6. Monitor errors, latency, task outcomes, and user feedback after launch.

    LLM-specific CI/CD integration should add prompt evaluation, golden datasets, and semantic checks to normal build steps. Together, these checks make prompt quality part of the evaluation pipeline and create explicit release gates.

    Set approval gates by risk

    A formatting change for internal summaries may need one reviewer and automated tests. High-impact financial, medical, legal, or customer-facing guidance needs stronger controls. Domain experts, including the appropriate product, policy, or domain owner, should approve it.

    Require code-owner approval for tool or schema changes. Require a product or domain owner to approve tone, policy, and business rules. Security review should cover new data sources, external actions, tools, and privilege changes.

    Test candidate prompts with a golden dataset

    A curated collection of inputs should represent the behavior you want. It supports prompt testing and connects each release to prompt versioning. Include ordinary requests, difficult edge cases, unsafe requests, incomplete context, adversarial attempts, and examples that previously failed.

    Keep each case small enough to explain. Store the input, expected properties, scoring rubric, and any required source facts. Don’t rely on a vague label such as “good answer.”

    A software release dashboard shows test comparisons, approval, deployment, and a rollback route.

    Score more than one outcome

    Layered evaluation gives you a clearer release decision. Run automated evaluation through evaluation pipelines in CI/CD and staging. Check valid JSON, required fields, policy phrases, citation format, latency, and token usage. Then use rubric-based review for helpfulness, groundedness, and tone.

    Use an LLM-as-a-judge carefully. Pin the model, model parameters, judge prompt, and scoring criteria, then sample results with human review. It’s a scoring aid, not an authoritative source of truth. It can compare candidates at scale, but it can also inherit blind spots.

    Run a side-by-side comparison between the current production version and the candidate. The candidate should meet its absolute quality threshold. Regression testing should also confirm that it doesn’t degrade behavior against the incumbent.

    Preserve the evidence

    Store evaluation outputs with the Git commit, including the golden dataset version, scorer version, pass rate, failure examples, and reviewer decision. Use failure examples and rubric scores to guide prompt optimization instead of subjective playground edits.

    Attach the prompt release ID to production traces. That record answers a difficult question quickly: did the problem start after a prompt change, a model update, a retrieval refresh, or a tool outage?

    Choose the right delivery pattern

    Prompt versioning can keep Git as your source of truth, even when a prompt platform handles delivery. The key decision is how your application obtains the approved prompt version.

    Different LLM applications need different delivery patterns for approved prompt versions.

    PatternHow it worksBest fit
    CI/CD packagingWith CI/CD integration, your build bundles a pinned prompt commit with application code.Strict change control and simple deployments
    Live prompt fetchingThe app retrieves an approved version by tag or release ID at runtime.Fast prompt updates without app redeploys
    Proxy or gateway controlA proxy gateway selects versions, models, and rollout rules at runtime.Multi-model systems and gradual releases

    CI/CD packaging gives you the strongest pairing of application and prompt code. However, urgent wording fixes require a new deployment.

    This approach separates prompt releases from application releases. It requires caching, availability planning, and access control over who can retrieve or promote an approved prompt. Keep a pinned fallback for outages, and ensure runtime requests resolve to an approved release in the production environment.

    A proxy gateway can support canary releases or percentage rollouts. Still, version and review the selection rules, or runtime routing moves complexity outside Git and weakens immutable history.

    Prompt management platforms such as LangSmith, Braintrust, and Agenta can add prompt registries, environment promotion, diffs, and evaluation workflows. Git remains authoritative when your team’s governance requires it, and LaunchDarkly can add governed rollout control. If you prefer a build-it-yourself route, the Awesome LLMOps collection is a useful starting point for evaluating open-source components.

    Roll back by repointing, not rewriting history

    A safe rollback restores a known release. Prompt versioning makes that known-good restoration possible. Do not edit an old prompt in place or force-push Git history. Those actions blur the evidence you need during an incident.

    Suppose version v1.4.0 changes a support agent to call an account lookup tool before answering billing questions. After release, latency rises and the agent starts timing out for some users.

    For prompt rollback, disable the new rollout or repoint the production tag to the approved immutable release, v1.3.2. Then preserve production traces before comparing the tool schema, timeout setting, model parameters, retrieval state, and model identity between releases. Open a new corrective branch after stabilizing production.

    Your rollback strategy should name the owner, approved fallback release, trigger conditions, and verification checks. Test it before an incident forces you to learn it under pressure.

    Frequently Asked Questions

    What is prompt versioning?

    Prompt versioning is the practice of storing prompts and their runtime configuration as reviewable, identifiable release artifacts. It allows teams to test, approve, deploy, monitor, and roll back prompt changes reliably.

    Is a Git commit enough to reproduce a prompt release?

    No. Reproducibility also requires the model, parameters, retrieval data and settings, tool definitions, output schema, input data, and evaluation results associated with the prompt.

    How should teams test prompt changes?

    Use a golden dataset that includes normal requests, edge cases, unsafe inputs, incomplete context, adversarial attempts, and previous failures. Combine automated checks for structure, policy, latency, and token use with rubric-based evaluation and human review.

    How should a team deploy a prompt safely?

    Promote an approved and evaluated commit through development, staging, and production using immutable release identifiers. Do not treat a merge to the default branch as production deployment without the required evaluation and approval gates.

    What is the safest way to roll back a prompt?

    Repoint production to a known-good immutable release or disable the new rollout without rewriting Git history. Preserve traces and compare the prompt, model, configuration, retrieval state, tools, and schemas to identify the cause.

    Build a release history you can trust

    Git-based prompt versioning records releases; settings, tools, schemas, retrieval data, tests, approvals, and traces make each record useful. A durable version history supports fast recovery and clear explanations when changes need review.

    Treat production prompts as software artifacts, with prompt management covering their maintenance, evaluation, promotion, and recovery. For LLM applications, version control for prompts combines human-readable instructions with machine-checkable evidence. When a release goes wrong, you can restore a known version quickly and explain why it was safe to ship.

  • Few-Shot Examples That Improve Model Accuracy

    Few-Shot Examples That Improve Model Accuracy

    A model can follow a vague instruction and still produce polished nonsense. Few-shot examples reduce that risk by showing the model what a correct input, decision, and output look like in your real task.

    The strongest demonstrations don’t try to teach every possibility. They give large language models a compact, representative pattern that helps them generalize to new requests.

    A reusable prompt template organizes the task instruction, demonstrations, and expected response. This selection principle applies across hosted systems and open-source models. It’s part of prompt quality, not just prompt length.

    Key Takeaways

    • Few-shot examples show a model what correct inputs, decisions, and outputs look like, helping it generalize without changing its model weights.
    • Start with a clear zero-shot baseline, then compare fixed and retrieved few-shot prompts on held-out inputs before adding demonstrations.
    • Choose representative, diverse, and well-labeled examples that include boundary cases and ambiguous inputs; keep their structure and output format consistent.
    • Use schemas for formatting, retrieve examples with diversity controls in dynamic workflows, and validate prompt performance across models, tasks, and failure types.

    Zero-Shot, One-Shot, and Few-Shot Examples

    Zero-shot prompting gives the model only an instruction. It works when large language models recognize the task and the desired format is simple, such as “Summarize this email in three bullets.”

    One-shot prompting adds one worked example. That single demonstration can clarify a label, voice, or JSON structure, but it rarely covers ambiguity. When more cases matter, few-shot prompting expands the pattern with several task-specific examples.

    When multiple demonstrations earn their place

    Use few-shot prompting to give the model several task-specific input-output pairs before the live request. These few-shot examples can support classification, extraction, rewriting, routing, sentiment classification, code generation, or content creation. Two to five examples may be enough, depending on the task.

    Use it when the model must learn a local rule that an instruction alone doesn’t state well. A system message can define the durable task, while task-specific examples clarify boundaries. For example, “urgent” customer messages may include refund threats, account lockouts, and service outages. A model needs examples of the boundary, not only a category definition.

    These demonstrations guide the model through in-context learning. They don’t change model weights. Instead, they establish a temporary pattern within the current prompt.

    Start with zero-shot as a baseline

    Don’t assume demonstrations improve every task. First, test a clear prompt template as a practical prompt engineering step on held-out inputs. Then add examples and compare model performance. Open-source models may need a different demonstration count.

    This baseline tells you whether examples add accuracy or only increase token cost. It also exposes tasks where a strict schema or a better instruction solves the problem without extra demonstrations.

    A demonstration is useful only when it changes decisions on realistic, held-out inputs, not when it merely lengthens the prompt.

    Choose Few-Shot Examples That Reflect Real Work

    The best few-shot examples resemble future inputs while covering different decisions. If you select five nearly identical cases, the model may repeat their pattern while mishandling the exceptions that create support tickets or bad reports.

    A person selects balanced data cards beside a laptop and rising chart.

    Use representative cases, not polished favorites

    Build a candidate pool from real, reviewed inputs drawn from your training data. Include common requests, ambiguous phrasing, short inputs, long inputs, and cases that were previously misclassified.

    For sentiment classification, a natural language processing task, don’t use only obvious praise and obvious complaints. Include “The product is fine, but delivery took two weeks” and define how your business labels mixed sentiment. Consistency beats clever wording.

    Research on retrieving in-context examples supports selecting task-relevant demonstrations for few-shot prompting rather than relying on one fixed block for every query. Still, relevance alone isn’t enough, so evaluate the same prompt template with different example sets. A retrieved set that contains four near-duplicates has weak coverage.

    Put boundaries and counterexamples in the set

    Include representative positive and negative examples, boundary cases, and ambiguous inputs that separate categories people often confuse. For a lead-routing prompt, show a sales inquiry, a billing question, an existing customer’s upgrade request, and a negative case for over-assigned labels. Check that coverage holds across the model family you’ll deploy, including open-source models.

    Define categories before selecting demonstrations. For a software-directory classifier, protect against label leakage by keeping category names out of user-query text unless they genuinely occur. Your examples may need to distinguish broad search intent from writing-tool intent:

    User queryCorrect category
    complete ai tools listGeneral AI Tool Directories
    best ai tools 2026top rated ai software
    ai tool directorycomprehensive ai list
    free ai tools listpremium ai software list
    new ai tools 2026General AI Tool Directories
    ai writing tools listContent & Writing AI
    best ai copywriter toolsai blog post generators
    ai grammar checkersai essay writing tools

    These labels work only when the taxonomy is stable and defined in advance. If editors disagree on whether a query belongs in a broad directory or a content category, repair that policy before asking a model to reproduce it.

    Set the Right Shot Count, Format, and Order

    Two to five few-shot examples are a practical starting range for many business tasks. Add a demonstration only when it covers a missing case or fixes an observed failure. More examples can dilute the instruction, consume the context window, and create conflicting signals.

    Keep every demonstration structurally identical

    Use the same fields, delimiters, null handling, and output format in every example. A consistent prompt template keeps the output contract stable, with durable instructions in the system message and a changeable demonstration block. If one output is prose, another is JSON, and a third is a loose bullet list, the model has no stable target.

    A weak extraction prompt leaves the format implied:

    Extract the company, contact, and budget from these messages.
    “Hi, I’m Maya at Northstar. We can spend about $8,000.”

    A better prompt makes the contract visible:

    Input: “Hi, I’m Maya at Northstar. We can spend about $8,000.”
    Output: {“company”:”Northstar”,”contact”:”Maya”,”budget_usd”:8000}

    Input: “I work for Amber Labs. Please contact Devon. Budget is undecided.”
    Output: {“company”:”Amber Labs”,”contact”:”Devon”,”budget_usd”:null}

    Input: “{{new_message}}”
    Output:

    The second example establishes how you handle missing values. That detail often prevents more errors than another ordinary example.

    Test example ordering rather than trusting a rule

    Sequence can affect output because recent content may carry more weight in a long prompt. Put a high-value boundary case near the end, then compare the original sequence with a shuffled version against your validation set. Keep answer labels and other target information out of input examples to avoid label leakage.

    Don’t treat “best example last” as a universal law. Recent work on sampling and prompt selection shows that selection strategy changes results across settings and model families, including open-source models. Measure the effect for your model, task, and prompt length rather than assuming it generalizes.

    Build a Production Workflow for Example Selection

    A static prompt works for a narrow, stable workflow. It becomes brittle when incoming requests span many products, languages, intents, or document types.

    Start with a reviewed pool of few-shot examples. Store each item with the input, expected output, task type, language, source, date, error tag, and training data provenance. Record the model family and deployment context, especially for open-source models. Track policy and instruction versions separately from retrieved examples, including the system message version, and remove outdated policy examples before production.

    Split-screen workflow compares static examples with ranked examples and validation results.

    Retrieve relevant examples with diversity controls

    For each new request, retrieve candidates that resemble its topic or structure. Use few-shot prompting to build a request-specific demonstration set. Insert the selected candidates into a prompt template before sending the request.

    A support question about an invoice should retrieve billing examples, not generic account examples. However, if every retrieved item says “refund,” the model may force the new request into that label. Set a diversity rule, such as limiting near-duplicates, requiring more than one class when contrast matters, and validating selections against real edge cases.

    For larger pools, use embeddings with retrieval-augmented generation in a vector store. Smaller pools can use a simpler metadata filter; either way, aim for a relevant, varied set rather than similar records.

    Clean labels before the model learns the wrong pattern

    One incorrect demonstration can contaminate a short prompt. Review noisy examples when human annotators disagree, model outputs conflict with recorded labels, or source data changes. For structured outputs, schema validation can catch malformed expected outputs, but it can’t fix a semantically incorrect label.

    Data-centric tooling can help prioritize review. Cleanlab’s label-issue detection workflow identifies suspicious labels in classification datasets. You still need human subject-matter review, because a flagged row may be an unusual but correct case.

    Place Examples Where the Model Can Use Them

    Message placement affects maintainability and behavior. Keep your system message focused on durable rules: role, safety constraints, allowed tools, and response standards.

    OpenAI’s prompting guidance recommends placing task-specific details and examples in the user message. This separation keeps the system message stable and makes task examples easier to version.

    Use chat turns or one compact example block

    For conversational tasks, few-shot prompting can use individual user and assistant turns to make the pattern clear:

    • User: “Customer says the package never arrived.”
    • Assistant: {"intent":"delivery_issue","priority":"high"}

    For extraction or classification, few-shot examples in a compact YAML-style or labeled block can be easier to inspect. A reusable prompt template should keep the live input visually separate from demonstrations. Without clear delimiters, the model may treat an old example as the live request. Test delimiters and turn structure with the deployed model family, including open-source models.

    Let schemas carry format rules

    If your API supports structured outputs or JSON Schema, use the schema to enforce field names, types, and the output format. Then reserve examples for judgment calls, such as category boundaries and missing-data treatment.

    This is a practical prompt engineering choice that lowers prompt clutter. It also prevents you from wasting shots on brackets, commas, and field order that the schema can control.

    Validate Accuracy Across Models and Failure Types

    Prompt quality isn’t a feeling. Good prompt engineering starts with a validation set that the prompt never sees during selection. Include frequent cases, edge cases, adversarial wording, and records from new sources.

    Track task-appropriate measures of model performance. Classification needs accuracy, precision, recall, and confusion patterns, with sentiment classification judged through confusion-matrix analysis. Extraction needs field-level correctness and compliance with structured outputs. Content workflows may need a human rubric for factual support, format compliance, and brand restrictions.

    Compare prompt variants under the same conditions

    Run zero-shot prompting and one-shot prompting on the same validation inputs. Compare them with fixed few-shot and retrieved few-shot versions using the same few-shot examples. Keep the model version, temperature, tools, output schema, prompt template, and system message constant.

    Log failures with enough context to diagnose them. A wrong answer may come from a noisy example, poor retrieval, an unclear instruction, excessive context, or an unstable label definition. Change one factor at a time.

    Open-source models may need more demonstrations than highly instruction-tuned hosted models. Large language models can have different ideal shot counts by model family, but that isn’t a reason to fill the context window. Use measured evaluation data, not assumptions, to choose the count.

    Treat reasoning models as a separate prompt family

    Reasoning models don’t always respond well to traditional demonstrations or chain-of-thought prompting. The DeepSeek-R1 research paper reports that few-shot prompting consistently degraded performance in its evaluation.

    For DeepSeek-R1 and similar reasoning-focused models, begin with a direct zero-shot instruction, clear constraints, and a schema where appropriate. Add demonstrations only after testing proves they help the actual task.

    OpenAI o1-style systems also deserve their own evaluation run. A pattern that improves a general chat model may distract a reasoning model or anchor it on superficial features.

    Frequently Asked Questions

    What are few-shot examples?

    Few-shot examples are task-specific input-output pairs included in a prompt before the live request. They show the model how to apply a local rule, classify an edge case, or follow a required response format.

    How many few-shot examples should you use?

    Two to five examples are a practical starting range for many business tasks. The right count depends on task complexity, prompt length, validation results, and the model family, especially for open-source models.

    How should you choose few-shot examples?

    Select examples that resemble real inputs and cover common cases, ambiguous phrasing, boundary decisions, and previous errors. Avoid near-duplicates, noisy labels, and examples that reveal the target label in the input.

    Do few-shot examples improve every model or task?

    No. Test zero-shot, one-shot, fixed few-shot, and retrieved few-shot prompts under the same conditions on held-out data. Reasoning-focused models may respond better to direct zero-shot instructions, while other models may benefit from carefully selected demonstrations.

    Make Every Demonstration Earn Its Tokens

    High prompt quality comes from disciplined selection, not a library of impressive-looking samples. Choose representative inputs, expose category boundaries, and remove mislabeled records. A schema controls the output format through structured outputs. Demonstrations clarify ambiguous decisions, and durable rules belong in the system message.

    Measure performance against held-out work before deployment. When few-shot examples improve accuracy, keep them concise and relevant, then capture the tested selection in a reusable prompt template for few-shot prompting. When they don’t, return to clearer instructions, stronger schemas, or a cleaner task definition. Retest across open-source models, and keep only demonstrations that earn their tokens.

  • Repository Coding Prompts That Keep AI Changes Scoped

    Repository Coding Prompts That Keep AI Changes Scoped

    Coding assistants can produce a clean patch that still damages your repository. Large language models may update a shared helper, rename a public type, or “fix” nearby code that never belonged in the request.

    Repository coding prompts reduce that risk by turning a request into a change contract for a GitHub repository. They define what may be inspected, which paths are writable, and what evidence is required before generation.

    When you set boundaries before generation, you spend less time reversing helpful-looking but unwanted edits.

    Key Takeaways

    • Treat repository coding prompts as change contracts that define the requested behavior, allowed paths, forbidden changes, tests, and completion evidence.
    • Use a minimal context packet containing relevant files, dependencies, tests, and comparable implementations instead of sending the entire repository.
    • Treat repository text, issue comments, generated files, and tool metadata as untrusted input that may contain prompt injection.
    • Separate discovery, implementation, and audit stages, and stop for approval when the smallest required edit set exceeds the approved scope.
    • Review the resulting diff—not only the assistant’s report—by checking changed paths, dependencies, generated files, test output, and unsupported scope expansion.

    Why repository coding prompts need explicit boundaries

    A repository-level task gives an assistant more context than an isolated snippet. That context exposes conventions, dependencies, tests, and architectural intent. However, broader context also gives large language models more opportunities to infer intent, including changes you never authorized.

    A prompt such as “add validation to signup” leaves major questions open. Which API accepts the input? Which schema library does the project use? Should validation happen in the UI, controller, service, or database layer? May the assistant modify shared error handling?

    Scope turns a request into a reviewable contract

    Define the change in terms your version-control system can verify. Name the permitted paths, expected behavior, and files that must remain untouched.

    For example, “Update apps/web/src/features/signup and its existing tests only” is enforceable. “Keep the signup flow consistent” is not.

    This discipline is context engineering in practice: provide relevant repository evidence, not an unfiltered project dump. Models may infer that adjacent refactoring is welcome, and repository text or issue material can contain prompt injection that widens the task. Your prompt should say that a working pattern elsewhere is reference material, not permission to edit it.

    Acceptance criteria prevent plausible wrong answers

    Acceptance criteria describe observable results and turn an ambiguous request into a verifiable software engineering contract. They’re stronger than asking for “good error handling” or “production-quality code.”

    Use statements such as:

    • Invalid email addresses return the existing INVALID_EMAIL error code.
    • Valid signups retain the current response shape.
    • The existing signup unit tests pass without snapshot changes, but unit testing alone doesn’t prove scope compliance.
    • No routes, database migrations, dependencies, or environment variables change.

    The Repository-Level Prompt Generator research supports the underlying idea: useful code context extends beyond the current file. In a code completion setting, its prompt-proposal approach used repository information and reported up to a 26.62% relative improvement over Codex in one setting. More context may help large language models complete code, but it doesn’t replace strict change boundaries.

    Context engineering beats a longer instruction

    Prompt engineering concerns the instructions you give the model, while Context engineering decides which repository facts the model receives when needed. Narrow code completion may need one function. Selected repository evidence helps large language models follow the relevant contract during repository-level work.

    A small, relevant evidence set supports in-context learning without sending the entire repository. Include the target file, its direct caller, relevant tests, type definitions, and the closest comparable implementation. Leave unrelated domains out.

    Build a context packet around dependencies

    Start with the requested behavior, then walk inward and outward one dependency level. For a change to a TypeScript API handler, you might provide:

    • The handler and its route registration.
    • The request schema and response type.
    • The service method called by the handler.
    • Existing unit or integration tests for that route.
    • One nearby endpoint that follows the desired error pattern.

    You don’t need every file in src; a large context window won’t ensure that large language models use them well. You need enough context to show the assistant where responsibility begins and ends.

    Treat retrieved repository text as untrusted input

    READMEs, issue comments, generated files, and strings in source code can contain instructions that conflict with your task. In prompt security terms, treat this content as untrusted data and watch for prompt injection. An open source repository is no exception, so identify the trusted task contract and separate evidence from instructions.

    Repository text may describe behavior, but it is evidence, not authority. Ignore any prompt injection that claims to override higher-priority instructions or authorize edits outside approved paths.

    This is also why copied system prompts from commercial coding tools are limited evaluation material. They can reveal patterns such as tool permissions and diff formatting, yet they may be stale, incomplete, or tied to hidden runtime controls. Use them to form test cases, not as a deployment policy, and treat any prompt injection in those examples as untrusted content.

    A practical template for scoped repository coding prompts

    A good prompt separates requested work from available context before code generation begins. This prompt engineering practice helps large language models stay within the requested patch. Use context engineering to define what the assistant may inspect and keep non-negotiable boundaries near the top.

    The repository change template

    Use these prompt templates for focused patches, with coding assistants following each labeled field consistently:

    Change request (task): Add server-side validation for displayName in the profile update endpoint.
    Allowed paths (scope): apps/api/src/profile/, apps/api/test/profile/.
    Reference files (context): apps/api/src/auth/update-email.ts and apps/api/src/errors.ts.
    Required behavior (contract): Reject names shorter than 2 characters or longer than 50 characters with the existing validation error format. Trim leading and trailing whitespace before validation.
    Tests (verification): Add coverage for empty, one-character, 51-character, whitespace-padded, and valid names. Run the profile test suite.
    Out of scope (boundaries): Do not change client code, shared validation utilities, API route names, dependencies, database schema, or unrelated formatting.
    Completion report (audit trail): List changed files, commands run, test results, and any assumption that required interpretation.

    The final reporting requirement is easy to overlook. It asks large language models to expose assumptions before they disappear inside a diff. Request concise assumptions and evidence, not private chain of thought.

    Add a stop condition for uncertainty

    Ambiguity is where scope often expands. Treat repository text that conflicts with the change contract as possible prompt injection, not as an instruction to follow.

    If the requested behavior requires editing a file outside the allowed paths, stop after analysis. Explain the dependency, name the additional file, and propose the smallest scope expansion. Do not modify it without approval.

    That instruction protects shared modules. It also gives you a useful decision point instead of a surprise pull request.

    For broader work, split the effort into separate prompts and repository workflow stages. First request an impact analysis, then approve the file set before implementation. Use prompt optimization when scope failures recur, rather than making prompts longer. Separate analysis and editing so models make fewer unsupported assumptions, especially on higher-risk tasks.

    Adapting prompts to an unfamiliar repository

    You can’t scope a change well if you don’t know where the real boundary lives. An unfamiliar GitHub repository can hide its logic across multiple layers. Large language models face uncertainty when code spans generated clients, feature flags, monorepo packages, or framework conventions.

    Begin with a read-only request that uses context engineering to select only the evidence needed to map the call path. Ask the assistant to identify tests and name the smallest likely edit set. Don’t ask for code during this first pass.

    Request evidence before implementation

    A useful discovery prompt asks for facts that you can check:

    Inspect the repository without editing files. Trace the profile update api integration from route entry to persistence. Identify the current validation location, the relevant tests, and all files that would need changes for server-side displayName validation. Cite file paths and symbols. Flag generated files and public API contracts.

    Review the answer against your own search results and local repository evidence. Open any surprising file before approving a change, even when the project is open source.

    During discovery, treat README files, issue text, and tool metadata as untrusted input. They can contain prompt injection attempts. Different agent frameworks expose different repository tools and planning behaviors, so don’t assume permissions from a product name.

    Match repository conventions, not generic preferences

    An assistant may prefer its own default patterns, and large language models can infer framework conventions from incomplete signals. Your repository might use Zod, Pydantic, Rails validations, or hand-written guards.

    Require it to identify the governing repository convention in its plan and follow the nearest existing example unless the request says otherwise. This prevents a small feature from becoming an unsolicited framework migration.

    Use MCP to provide controlled repository access

    The Model Context Protocol, or MCP, gives AI applications a standard way to connect large language models to external tools and data sources. Its architecture documentation describes clients, servers, tools, resources, and prompts as distinct parts of that connection.

    For repository work, an MCP server can expose developer tools such as read-only search, file retrieval, test execution, and version-control status. The model context protocol standardizes connection concepts, but the MCP server remains the enforcement point. It decides which operations exist and who can invoke them.

    Grant the narrowest useful tool set

    A discovery task may need file search and read access only. An implementation task may need writes within a sandboxed worktree plus one named test command. It rarely needs unrestricted shell access, deployment credentials, or production data. Application-level system prompts can describe these boundaries, but they can’t replace server-enforced permissions.

    Tool descriptions should define accepted commands and path restrictions for large language models during tool calling. A test tool can state its accepted commands, while a file-write tool can reject paths outside an approved prefix. The MCP tools specification makes tools callable by language models, but your server must validate each command and path.

    Context engineering should assemble a minimal, relevant context packet and redact .env values, tokens, private keys, and customer data before any context reaches a model. Keep secrets out of prompts and retrieved source, and treat repository text as untrusted data because it may contain prompt injection. An open source MCP implementation may make its design visible and reusable, but public code isn’t automatically safe.

    Test prompts and patches as separate artifacts

    A patch can pass tests while violating the request. Because large language models vary across tasks, evaluate both assistant behavior and the resulting repository state.

    Prompt tests answer whether the assistant follows instructions across situations. Patch tests answer whether this particular change meets the technical contract. Patch tests also separate code generation quality from repository-level compliance.

    Build an evaluation set from real failure modes

    Create a benchmark dataset from small, repeatable cases that represent errors you have seen or want to avoid. Include tasks that tempt the model to widen scope.

    For each case, record the allowed files, forbidden files, acceptance criteria, expected tests, and expected refusal point. Add a prompt injection case where repository text attempts to authorize a forbidden edit. Then check whether the model:

    • names the correct files before editing;
    • avoids dependency changes and unrelated refactors;
    • stops when a required edit falls outside scope;
    • reports every modified file and test command honestly;
    • refuses or pauses when the requested action exceeds its authority.

    Promptfoo’s coding-agent evaluation guide covers testing agent workflows across several coding-agent SDKs and plain LLM setups. Use context engineering to keep supplied repository context consistent, then compare revised prompts through prompt optimization against fixed fixtures. Use an evaluation framework as repeatable infrastructure for running those prompts across agent frameworks where relevant.

    Score the diff, not only the prose

    A model can produce a reassuring completion report while its patch changes a forbidden file. Inspect git diff --name-only, lockfiles, dependency manifests, generated files, snapshots, and captured test output.

    Unit testing checks behavior, but these separate checks verify scope and evidence. Passing tests don’t prove instruction compliance. Large language models can satisfy tested behavior while violating repository boundaries.

    DeepEval supports pass thresholds and custom metrics in its agent evaluation guidance. For scoped code work, a custom metric can fail any run that touches a forbidden path, includes an unsupported dependency addition, or claims tests passed without captured output. These pass/fail metrics evaluate an agent workflow, not reinforcement learning or model training.

    Passing tests prove behavior at tested boundaries. They don’t prove that the assistant stayed within the agreed repository scope.

    Review AI-generated changes with an audit mindset

    Before merging, compare the diff with the original contract line by line. Start with paths, because a forbidden edit is often more important than an elegant implementation.

    Next, inspect for hidden scope expansion. Watch for lockfile changes, new packages, renamed exports, altered defaults, regenerated code, modified snapshots, and formatting churn. Each may be legitimate, but each needs an explicit reason.

    Ask for evidence-backed architectural reports

    For higher-risk changes, request a separate read-only audit from the coding assistants. They should cite paths, symbols, call relationships, and tests for every finding. Reject statements such as “this may cause issues” when they lack code evidence.

    A reassuring explanation from large language models isn’t evidence that the diff obeys the contract. Check repository text, generated files, and tool output for unexpected instructions or prompt injection that may expand scope.

    Use the same file-classification and evidence requirements across agent frameworks. Ask the follow-up audit to classify every changed file as required, justified collateral, or unrelated. Each classification should cite the requirement or dependency that supports it.

    If it can’t justify a file with a requirement or dependency, remove that change before merge. Evidence-backed review is a normal software engineering control, not distrust of automation.

    Frequently Asked Questions

    What is a repository coding prompt?

    A repository coding prompt turns a coding request into a change contract for a GitHub repository. It specifies the allowed paths, relevant context, required behavior, verification steps, out-of-scope changes, and completion report.

    How much repository context should a coding assistant receive?

    Provide a small context packet with the target file, direct dependencies, relevant types, tests, and the closest comparable implementation. Unrelated files add noise and do not guarantee that large language models will use the context correctly.

    Why should repository text be treated as untrusted input?

    READMEs, issue comments, generated files, and source strings can contain instructions that conflict with the task or attempt prompt injection. Treat them as evidence about the repository, not as authority to change the approved scope.

    What should an assistant do when a required change falls outside the allowed paths?

    It should stop after analysis, explain the dependency, identify the additional file, and propose the smallest scope expansion. It should not modify the file without approval.

    How can teams verify that an AI-generated patch stayed in scope?

    Inspect the diff and changed-file list, including lockfiles, dependency manifests, generated files, and snapshots. Compare those changes with the contract, review captured test output, and require an evidence-backed explanation for every modified file.

    Keep the contract smaller than the codebase

    Reliable repository work starts with a bounded request, a minimal context packet, and explicit acceptance criteria you can test. Controlled tools and an auditable diff make the result easier to review and trust. Give large language models permission to do less than they can technically access.

    When you treat scoped repository prompts as change contracts, you get diffs that are easier to review, test, and trust. The strongest prompt doesn’t ask for more initiative. It gives the assistant fewer ways to make an unapproved decision.