A fluent response from a large language model can still break your product. It may return malformed JSON, make an unsupported claim, edit the wrong file, or call a tool with unsafe arguments.
Prompt contracts turn a loose instruction into a testable behavioral specification. You define what the model receives, what it may produce, what must remain true, and how the system responds when the request is incomplete or unsafe.
That discipline moves your work beyond vibe coding and toward AI behavior you can inspect, test, version, and improve.
Treat prompt contracts like API contracts
A traditional API contract tells callers what to send, what they get back, and which errors to expect. Large language models are probabilistic, so a prompt contract cannot force identical wording. It can still define important boundaries and invariants, conditions that must remain true.
Replace implied requirements with explicit rules
“Write a product comparison” leaves too much open. Prompt engineering clarifies intent, but application rules determine what the system can enforce. A useful contract states the allowed source material, target audience, required sections, word limit, output format, and unsupported actions.
For a research assistant, you might require supplied sources before it makes a factual claim. For a coding agent, you might limit changes to named files. For a support bot, you might require a clarifying question when the account context is missing.
The goal isn’t simply shorter prompts. It’s fewer assumptions and token efficiency that preserves necessary context.
Separate the prompt from its enforcement
Prompt wording establishes intent, but code must enforce requirements that software can verify. Your application should parse JSON, reject missing fields, restrict tool arguments, and block actions outside approved scope.
Claude’s structured output documentation describes schema transformation and automatic validation helpers. Those capabilities reduce parsing failures, although they don’t prove the content inside a valid response is accurate. An API contract describes an interface, while application code still validates model output.
A valid JSON object can still contain a fabricated answer. Structural validation and factual validation are separate checks.
Define the five jobs of a contract
A practical contract gives the model a bounded job and gives your application a reliable way to judge the result.
State inputs and preconditions
Inputs include more than the user’s latest message. Record the system instructions, retrieved context, conversation history, tenant settings, tool results, model settings, and any policy constraints.
Preconditions say when work may begin. They should also establish invariants for valid work, such as required fields and allowed operating conditions. A travel assistant, for example, may need destination, date range, and traveler count. If any required field is absent, the contract should require a clarification rather than a plausible guess.
Also define trust levels. User text, web pages, uploaded files, and tool responses can contain instructions, but they should never override your system rules.
Specify outputs, evidence, and scope
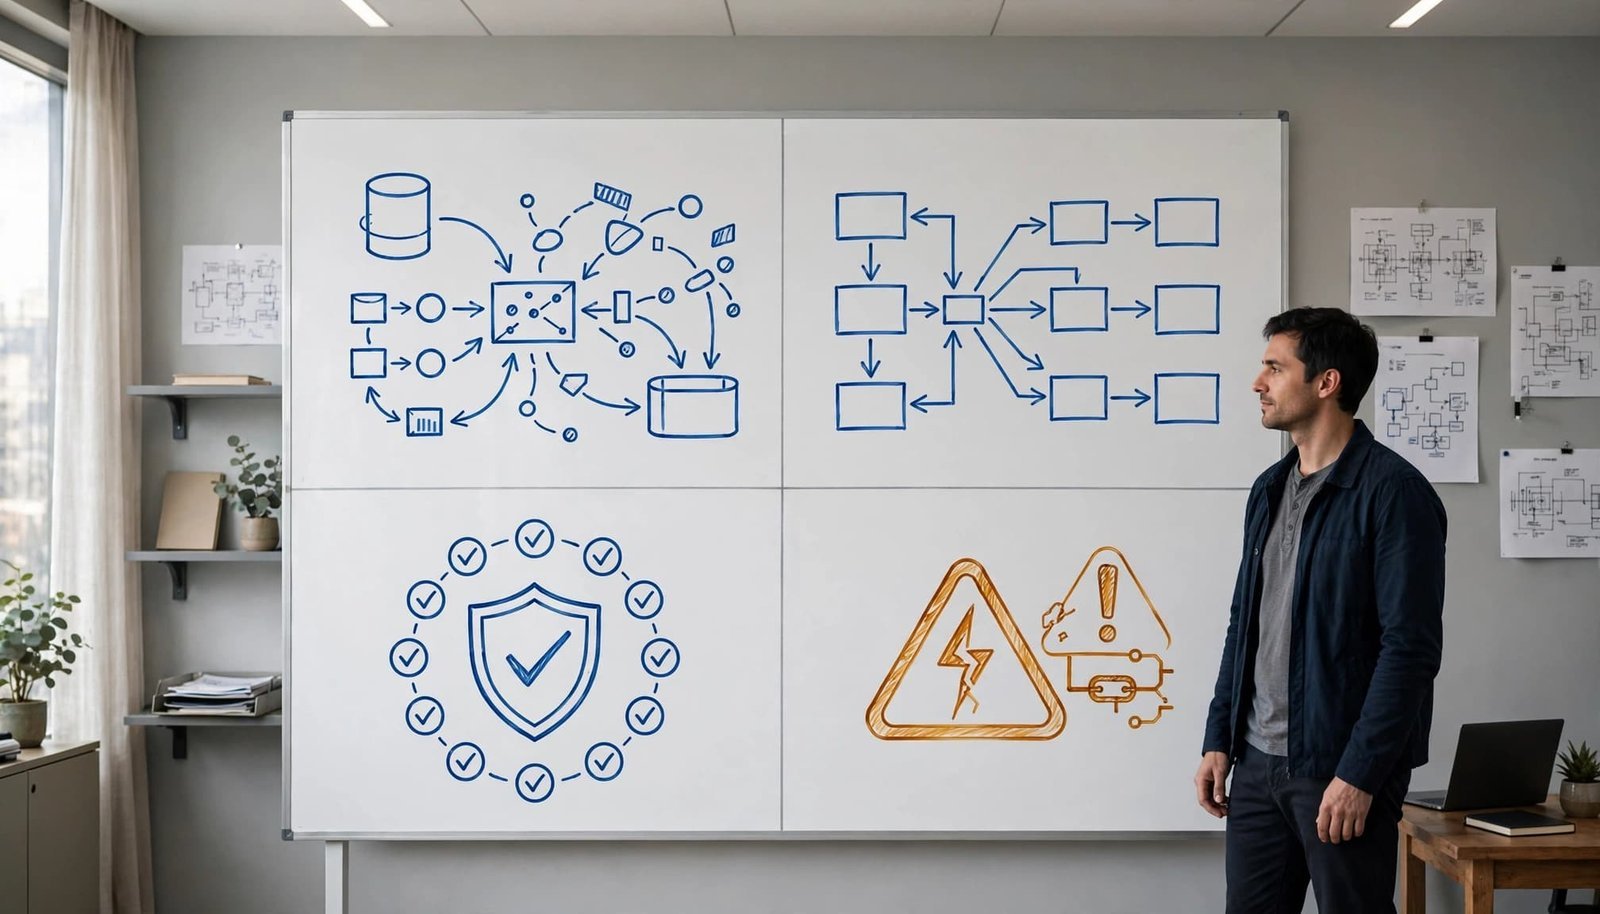
Your output schema should name required fields, permitted values, data types, and evidence requirements. An editorial workflow might return title, summary, claims, sources, and uncertainties. A coding workflow may return a patch plan, changed files, tests run, and unresolved risks. A behavioral prompt contract goes beyond a type contract or machine-enforced schema. The output schema defines shape, while invariants define behavior and protected conditions.
Scope control is equally important. Tell an agent which repositories, directories, tools, and actions it may use. Then state the invariants, or conditions that must remain true, such as “do not change public API signatures” or “do not alter authentication rules.” Check permitted tools and actions against these conditions before allowing the work to proceed.
Use a 5c prompt contract when you need a compact prompt contract
The 5c prompt contract, described in a 2025 paper, is a compact prompt-engineering structure for routine interactions with less cognitive overhead. Its cognitive architecture organizes how a model receives a task, constraints, fallback behavior, and presentation guidance. It isn’t a literal reasoning trace, API schema, or substitute for executable tests.
Character, Cause, and Constraint
Character identifies the operating role, such as a procurement analyst or TypeScript test reviewer. Cause states the job and intended outcome. Constraint lists non-negotiable rules, including allowed data, prohibited claims, output length, file boundaries, and other invariants.
For example, a marketing research prompt could instruct the model to act as an evidence-focused analyst, compare only supplied vendor records, and label unknown pricing as unavailable. That is more reliable than asking it to “find the best options.”
Contingency and Calibration
Contingency defines fallback behavior. It may require the model to ask a question, return an insufficient_context status, abstain, or escalate for review.
Calibration adjusts tone, detail, and output shape. You might request concise executive language, a neutral editorial voice, or a JSON object that matches a schema. Concise output requirements can also improve token efficiency.
Use 5C for focused, repeatable tasks. For repository edits, regulated decisions, or multi-step agents, add explicit tests, tool rules, and acceptance criteria around it.
Build a fuller contract for AI-generated code
Software tasks require more detail because small omissions can lead to broad and expensive changes. A fuller coding contract can extend a lightweight 5c prompt contract into eight sections: objective, preconditions, invariants, exact file scope, implementation contract, test-first specification, acceptance criteria, and anti-patterns.
The prompt contract should not be confused with API schemas, type contracts, or validators. Those tools enforce machine-checkable structure, while the coding contract defines intent, scope, invariants, acceptance criteria, and prohibited changes.
Set the objective, boundaries, and invariants
Write one outcome that a reviewer can recognize. “Add server-side validation for invitation expiry” is clearer than “improve invitations.”
Then name the permitted files and dependencies. Use scope control to state what must not change, including database migrations, existing endpoint shapes, or permission checks. These invariants protect endpoint behavior and authorization rules. An agent should propose extra files before touching them, not decide unilaterally.
List anti-patterns to make hidden risks visible. You might prohibit broad refactors, new packages, disabled tests, silent error handling, or changes to generated files. The contract should also prohibit changes to production code outside the approved scope.
Make acceptance criteria executable
Acceptance criteria should describe observable behavior. Require compilation, formatting, linting, type checking, unit tests, and static analysis as separate checks within a verification gate. Use test-driven prompting to define observable tests or a test plan before implementation. Ask for Arrange-Act-Assert tests that exercise public behavior rather than duplicate internal implementation details.
For a function with many branches, require a test plan before code, including relevant edge cases. However, reviewing the patch, test fixtures, and command results is different from evaluating hidden algorithmic reasoning. Don’t treat private model reasoning as test evidence, and avoid unnecessary cognitive overhead during review.
A contract becomes useful when a failed test points to a requirement that someone can fix. Clear anti-patterns also help reviewers identify prohibited behavior without guessing.
Validate outputs and define graceful failure
Production-grade reliability comes from a pipeline around the model, not prompt text alone. Validation catches hard failures before an answer reaches a customer or autonomous tool.
Run deterministic checks first
Use input validation for incoming fields and tool arguments. Check required keys, enums, string lengths, numeric ranges, URLs, citation fields, and permitted tool names with JSON Schema, Zod, or comparable validators. These checks are inexpensive and explainable, including for edge cases such as boundary values and missing fields.
Make structural validation the first verification gate. If wording may vary, use a narrow semantic rubric afterward. A judge can assess whether an answer follows supplied policy or addresses the user’s goal. It should not decide whether valid JSON has the required keys.
Structured-output and function-calling patterns help you connect model responses to predictable application behavior across common LLM providers. Keep semantic evaluation separate from factual verification when claims require evidence.
Distinguish bad answers from transient errors
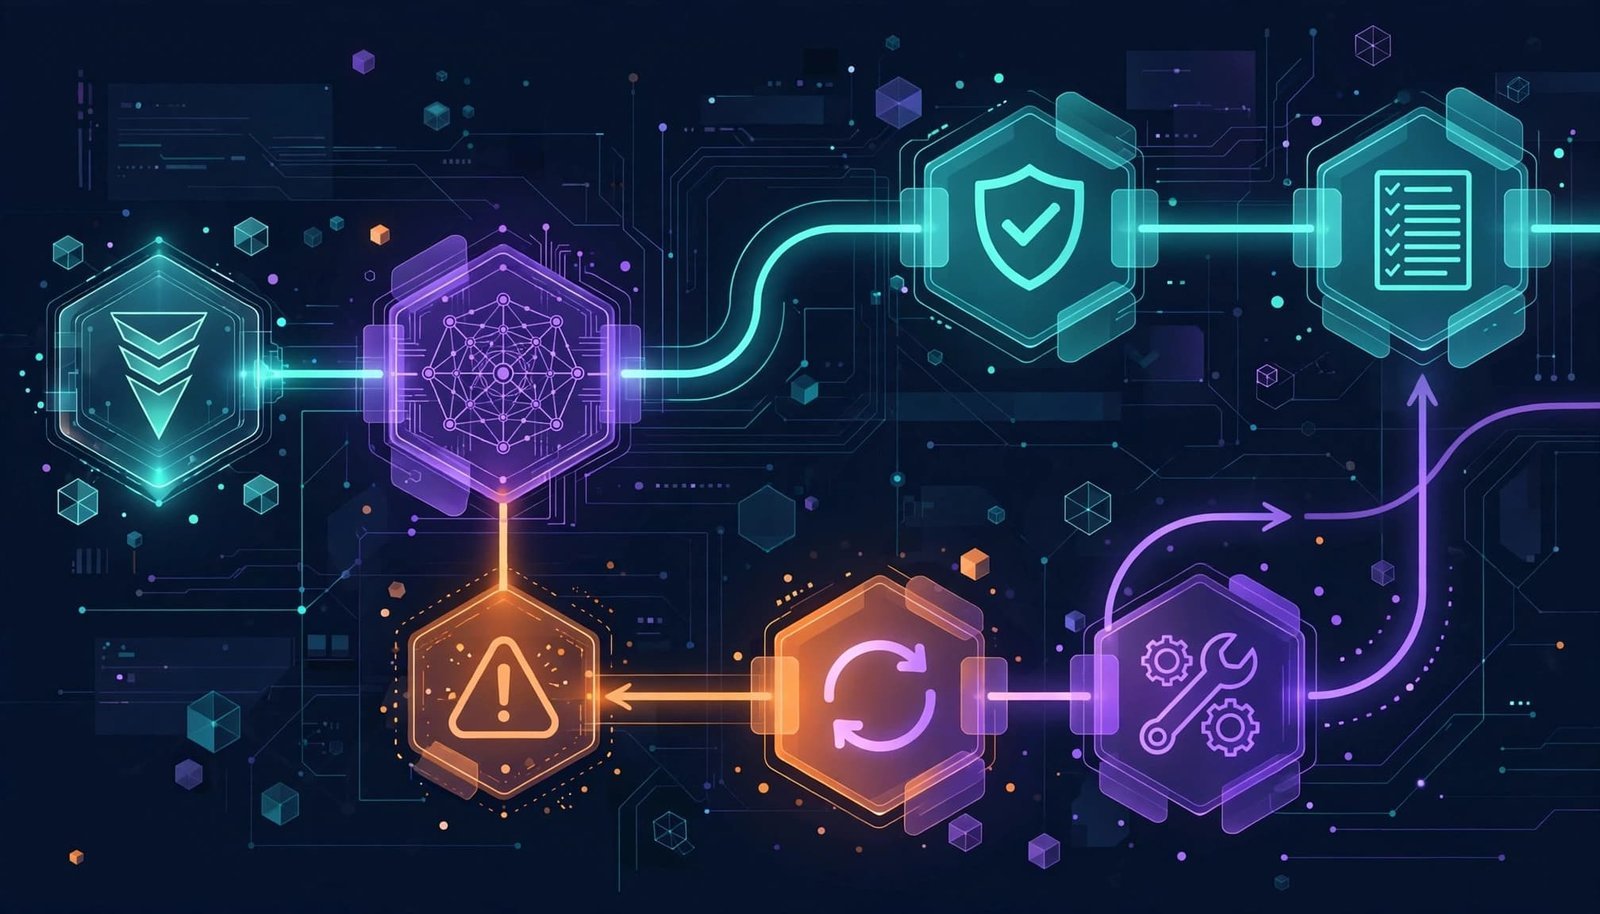
Clear failure modes separate transient provider errors from invalid answers. A timeout, rate limit, or temporary provider failure may justify a bounded retry with backoff. An invalid schema, unsafe tool call, or unsupported claim needs a repair instruction, fallback response, or human review path.
A bounded repair loop can follow an actionable repair instruction. It shouldn’t silently retry unsafe or unsupported output. Track token efficiency when measuring retry costs, and confirm invariants still hold after validation or tool execution.
Failure states should be named and actionable:
invalid_inputmeans required fields are absent or malformed.insufficient_contextmeans the available material cannot support a reliable answer.policy_refusalmeans the request violates a defined safety or access rule.tool_unavailablemeans a dependency failed after the allowed retry limit.validation_failedmeans the response did not meet its output contract.
Protect contracts against ambiguity and injection
Ambiguity is a product condition, not a model defect. Your contract should state when the model may infer a reasonable default and when it must request clarification.
A 5c prompt contract uses its Contingency element to define clarification, abstention, or escalation behavior.
Keep untrusted instructions in their place
Prompt injection occurs when content attempts to override the model’s intended behavior. A webpage might say “ignore all previous instructions,” while an uploaded document may try to extract protected data.
Define invariants so external content can’t override system rules or protected behavior. The OWASP prompt injection guidance treats this as a core risk for LLM applications. Treat external content as data, delimit it clearly, limit tool permissions, and validate any action before execution.
Input filtering helps, but it can’t solve the problem by itself. Your architecture needs least-privilege tools and approval gates for consequential actions.
Refuse accurately and without invented success
A contract should prohibit the model from claiming it sent an email, changed a record, completed a purchase, or verified a fact unless a trusted tool result confirms it.
When a tool fails, use a bounded, permission-aware repair loop. Never use it to retry a prohibited action indefinitely. Return a user-appropriate status without exposing secrets, internal stack traces, or access details. OWASP’s prevention cheat sheet also recommends input sanitization alongside output monitoring and validation.
Version contracts and log the evidence
Prompt text is release behavior. Store your schema, examples, fixtures, model settings, and evaluation rules in version control. For compact workflows, version the 5c prompt contract and preserve its stable cognitive architecture across releases.
Review behavior changes, not only wording
A pull request should reveal whether you changed source-grounding rules, allowed tools, refusal behavior, or output fields. Use test-driven prompting by versioning prompts and behavioral tests together. Otherwise, reviewers can’t tell whether a new prompt still meets the old contract.
Run the same fixed fixtures before and after a change. Compare the results against your acceptance criteria, including invariants such as required fields and refusal behavior. For variable tasks, measure pass rate, lowest score, latency, token use, token efficiency, and error count across repeated executions.
Capture useful observability without leaking data
Log the contract version, model identifier, validator outcome, tool name, tool result status, latency, and token counts. This evidence helps you locate whether a failure began in retrieval, generation, parsing, or tool execution.
Logging evidence doesn’t mean storing raw sensitive prompts and completions by default on sensitive routes. Redact personal data, access tokens, account numbers, and health details. Keep detailed traces access-controlled and retain them only as long as your incident process requires.
Apply prompt contracts to AI content recommendations
Content systems need contracts because polished prose can disguise weak research. For a general AI tool directory, contract invariants should cover duplicate domains, evidence-backed categories, current links, and dated pricing. A complete AI tools list or comprehensive AI list should flag incomplete records instead of presenting them as current.
A page about the best AI tools 2026, top-rated AI software, or new AI tools 2026 needs stated selection criteria and attributable evidence. Distinguish a free AI tools list from a premium AI software list, and never turn sponsored placement into an objective ranking.
Content and writing AI require task-specific rules. An AI writing tools list shouldn’t use the same rubric as the best AI copywriter tools, AI blog post generators, AI grammar checkers, or AI essay writing tools. Define whether you’re judging factual grounding, brand control, grammar accuracy, citation quality, privacy terms, or workflow fit.
Key Takeaways
- Treat each prompt as a versioned interface with defined inputs, outputs, assumptions, tool limits, and failure states.
- Put fixed requirements and invariants in code, including schemas, allowed actions, factual sources, and sensitive-data checks.
- Use clarifying questions, abstention, and bounded retries instead of guesses and silent loops.
- Test happy paths, missing context, boundary cases, tool failures, and adversarial inputs against clear acceptance criteria before release.
- Keep logs that connect model behavior to the contract version without storing sensitive content carelessly.
Frequently Asked Questions
What is a prompt contract?
A prompt contract is a structured specification for an LLM interaction. It defines the task, accepted inputs, preconditions, output format, behavioral limits, validation rules, and fallback behavior.
It doesn’t make a model deterministic. It makes the system’s expected behavior clearer and easier to test.
How do prompt contracts prevent vibe coding failures?
They replace vague requests with scope limits, invariants, acceptance requirements, and explicit error handling. For coding agents, that means you can restrict file changes, require tests, and reject changes that violate public interfaces.
The surrounding application must still validate the result. A prompt alone can’t stop a bad parser, a broken tool, or an unsafe permission model.
Should every prompt use JSON Schema?
No. Use a schema when downstream software needs predictable fields or when the output triggers an action. Free-form writing can use an editorial contract with source rules, prohibited claims, and semantic evaluation instead.
You can also mix both approaches. Return structured metadata for validation while keeping the final customer-facing prose flexible.
Build for accountable AI behavior
Prompt contracts help you stop treating a polished response as proof that an AI workflow worked. A 5c prompt contract suits compact tasks, while a fuller contract offers more control. Both can define the job, constrain risk, validate results, and preserve evidence when something fails.
The strongest contract is one your application can test and your team can review, balancing clarity, reliability, and token efficiency.
Leave a Reply