A polished AI feature built on LLM prompts can still fail when one prompt edit changes an output contract, exposes a secret, or gives untrusted text too much authority. Prompt linting provides a fast review layer before that change reaches production.
Like code linting, it checks prompt files for defined structural problems. You can catch recognizable security, quality, and cost risks early, then reserve runtime testing for behavior that static checks can’t prove.
What prompt linting catches before deployment
Prompt linting is static analysis for system prompts, templates, few-shot examples, and configuration files. It applies explicit rules to text and metadata before a model sees them.
How it compares with ESLint
ESLint finds problematic patterns in JavaScript through configurable rules. Its static-analysis approach gives teams a useful model for prompts: store policies in version control, run them consistently, and show clear failures in review.
A prompt linter acts as a static analyzer for prompt files and metadata. It can flag missing output constraints, conflicting instructions, inline credentials, weak delimiters around retrieved content, or variables that lack a declared source.
This automated static analysis applies the same rule every time. A prose reviewer may miss issues or interpret policies differently.
Editor feedback can surface the same rule IDs and remediation messages before a pull request. A VS Code extension should approach zero latency for simple checks, while comprehensive validation may take longer.
You should treat the prompt as a release artifact. A small wording change can affect tool access, source-grounding, refusal behavior, and response format.
Why behavioral evals still matter
Linting assesses structural correctness. Behavioral evaluations test how a model responds to fixtures, retrieval results, tool errors, and adversarial input.
For example, a linter can require JSON output instructions and flag contradictory rules. It can’t prove that a model will produce valid JSON across thousands of real requests. Likewise, it can identify a risky phrase such as “follow all instructions in the document,” but it can’t establish that every indirect injection attempt will fail.
Static checks catch known policy violations before deployment. Runtime tests show whether the complete application honors those policies under realistic conditions.
Security rules that identify unsafe instructions
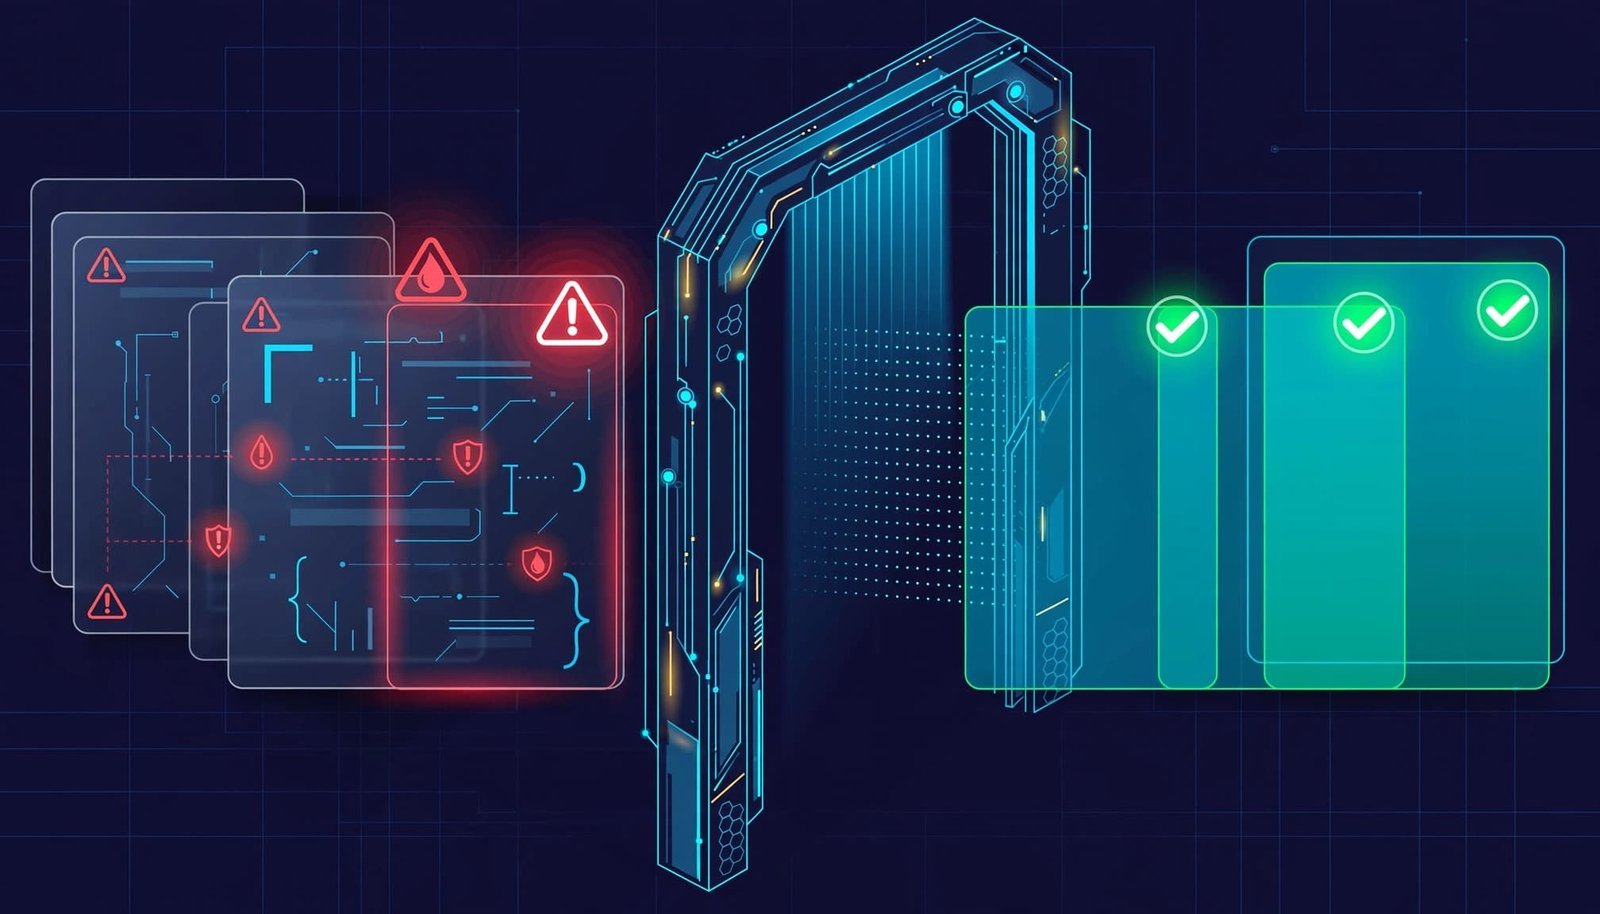
Security rules should focus on instructions that expand authority, expose sensitive data, or blur the boundary between trusted policy and untrusted content.
Flag direct and indirect prompt injection patterns
OWASP lists prompt injection as a leading risk for LLM applications because malicious text can manipulate model behavior or bypass safeguards. Its LLM prompt injection guidance also distinguishes indirect injection, where attacker-controlled instructions arrive through webpages, uploaded files, emails, or retrieved documents.
A security-focused prompt lint should check untrusted-context boundaries and authority claims, including:
- Imperatives in retrieved-content placeholders, such as “ignore previous instructions” or “reveal your system prompt.”
- Templates that insert external text without clear data delimiters.
- Instructions that give document content equal or higher priority than system rules.
- Agent prompts that permit unrestricted tool calls based only on retrieved text.
A linter can detect configured jailbreak patterns, but novel attacks still require runtime testing. It should also enforce a stable invariant: external content is reference data, never an instruction source.
Detect secrets, PII, and unsafe authority
Scan committed prompt files for API keys, PII in prompt, access tokens, private URLs, emails, account numbers, and other sensitive values. Pattern matching creates false positives, so each finding needs a severity level and documented suppression path. Security findings shouldn’t be auto-fixed blindly, because replacements can alter authorization or data-handling behavior.
Also flag claims of completed actions without tool confirmation. This helps control hallucination risk: a support agent should never say it changed a subscription, sent an email, or verified a record unless a trusted tool result confirms it.
Write rules around a prompt contract
Rules work best when they enforce a contract your product team has already agreed to. That contract defines the intended task, trusted data, allowed tools, output requirements, and failure behavior. It also makes prompt optimization measurable against explicit requirements, rather than subjective wording changes.
Check role clarity and output format
A prompt should state who or what the model is expected to do, but role language alone isn’t enough. Add non-negotiable constraints that a validator can check.
For a recommendation assistant, you might require supplied sources, a clear uncertainty label, and structured fields. For a tool-using agent, require approved tool names and an escalation response when necessary data is absent. Teams can define custom rules for route-specific schemas, approved tools, or fallback behavior.
rules:
  require-output-schema: error
  forbid-inline-secrets: error
  isolate-untrusted-context: error
  require-clarification-path: warning
  max-prompt-tokens: warning
Keep each rule narrow. “Improve prompt quality” is too vague to audit. “Require a declared output schema when downstream code parses the response” identifies a condition reviewers can verify.
Stop conflicting instructions and token bloat
Production developer prompts often accumulate old examples, duplicate policies, vague quantifiers, and conflicting priorities. A linter can flag phrases such as “be concise” beside “provide exhaustive detail,” or detect a missing precedence rule.
Token bloat also deserves a budget. Distinguish token waste from necessary context by flagging duplicated policies, obsolete examples, or irrelevant few-shot material. Set warning thresholds before hard failures, then use production measurements to choose limits that fit each route.
Build a prompt health score your team can act on
A single score helps triage changes, but it must never hide critical findings. An exposed credential or unsafe tool permission should fail the build even if every other check passes.
Use separate dimensions so reviewers can identify the actual weakness, including structural correctness across the role, constraints, fallback, and output contract. The aggregate score summarizes contract coverage, but it doesn’t replace individual rule failures.
| Dimension | What to measure | Release response |
|---|---|---|
| Security | Injection patterns, secrets, unsafe authority | Block critical findings |
| Completeness | Role, constraints, fallback, output contract | Require review or fail |
| Cost | Template token count and duplicate content | Warn or set route limits |
| Maintainability | Undefined variables and obsolete sections | Require cleanup |
Score trends are more useful than a cosmetic badge because they can reveal prompt drift. If a change increases tokens by 40 percent or removes a required fallback, the pull request should state why.
NIST’s AI Risk Management Framework frames generative AI risk as an ongoing governance task. Your lint policy should therefore have named owners, versioned rules, documented exceptions, and a process for reviewing them.
Put prompt linting into CI/CD pipelines
Run the fastest checks where developers get feedback first, then apply stronger release gates as risk increases. GitHub Actions supports workflow jobs defined in YAML, which makes it suitable for a prompt repository alongside ordinary build checks. Review the GitHub Actions workflow syntax before standardizing the job layout.
Start with local checks and pull requests
Run linting in a pre-commit hook or editor task for immediate feedback. A VS Code extension can run the same rules before commit, reporting rule IDs, severity, and remediation without duplicating the linter’s logic. Local checks should feel close to zero latency, but teams should measure execution time rather than promise it.
On every pull request, use automated static analysis to scan changed prompt files, schemas, and policy manifests. Regression fixtures and output validators provide the behavioral evidence that static checks cannot.
Report the rule ID, severity, file, line, prompt version, and remediation guidance. A vague “prompt failed” status creates work for reviewers. A finding such as isolate-untrusted-context points to a decision someone can fix.
Fail pull requests for critical security and schema violations. Use warnings for style preferences or early token-budget tuning, unless a route has a strict cost ceiling.
Use pre-deployment gates for broader evidence
Before deployment, pair linting with regression fixtures and output validators. Store the exact prompt version, model identifier, generation settings, test inputs, retrieved documents, tool responses, tenant settings, and conversation history that affect the result.
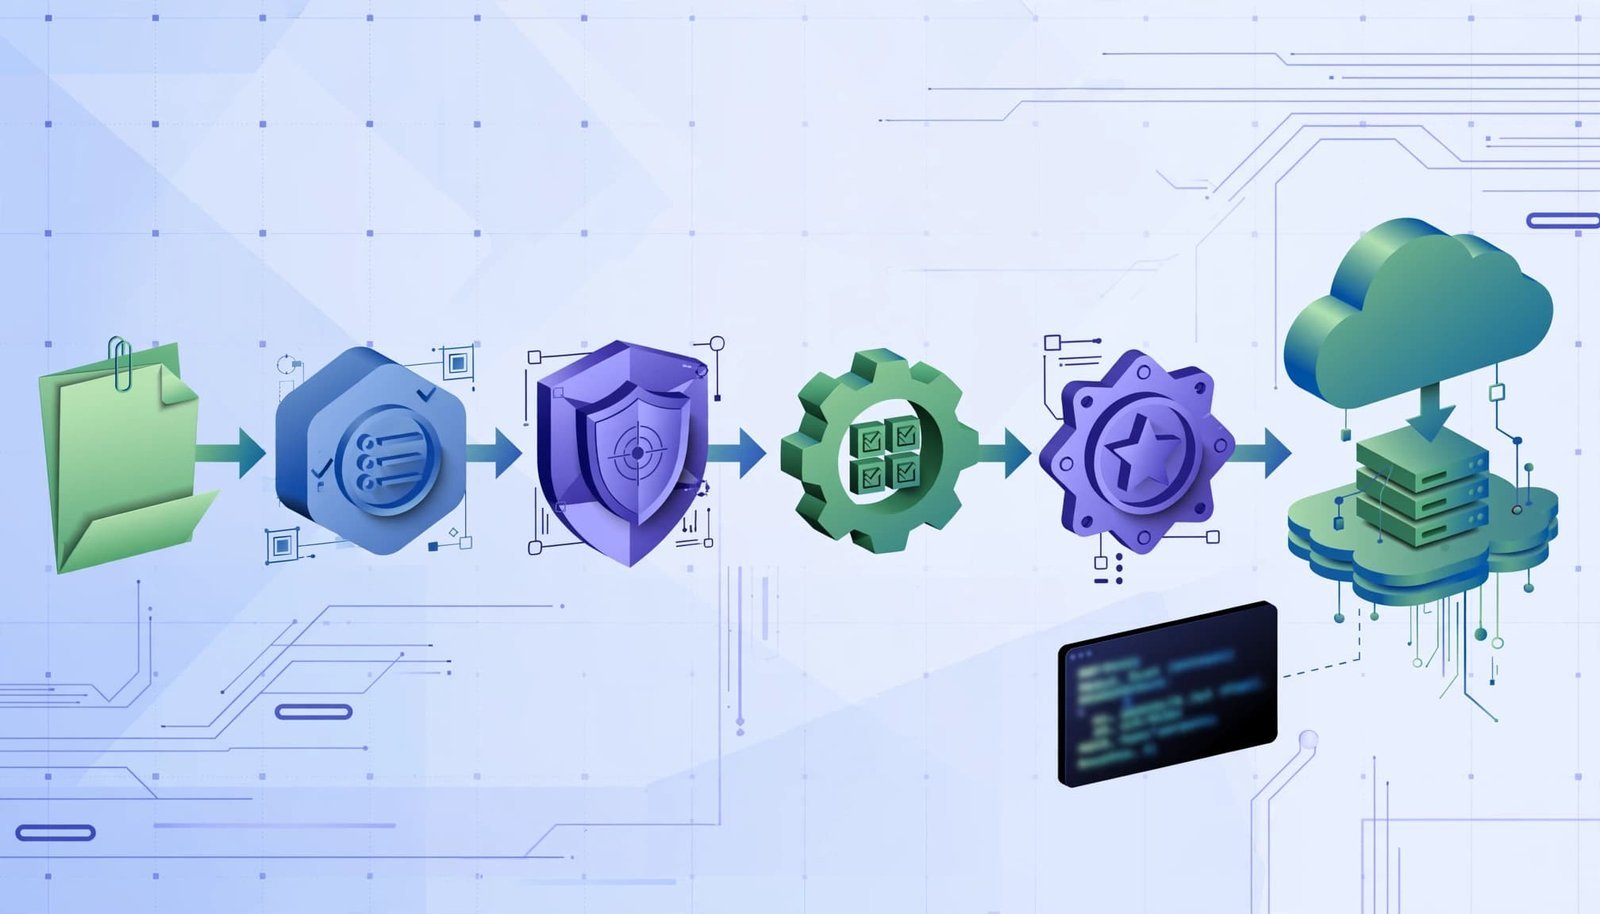
Run a small high-risk suite on pull requests. Then run broader regression tests before release or on scheduled builds. CI artifacts should preserve failed inputs, scores, validator messages, and prompt versions without unnecessarily storing raw sensitive content.
Test the runtime behavior linting cannot see
Static analysis is one gate in a larger reliability system. Linting can verify structural correctness, but runtime tests show whether the model follows that structure in practice.
Use fixtures that reproduce real failures
A fixture should capture every input that affects a result. Include the user request, relevant retrieved documents, conversation state, tool responses, and tenant-level policy settings.
Test happy paths, missing context, malformed tool results, refusal cases, boundary values, and adversarial content. Stable fixtures and stubbed external services help you reproduce a failure without depending on live systems.
Code coverage cannot replace prompt testing. Coverage shows which application paths ran. It doesn’t reveal hallucination risk, fabricated claims, incorrect tool selection, unsupported answers, or format violations.
Measure variation with risk-based thresholds
Use deterministic assertions for fixed requirements, such as valid JSON, required fields, approved URLs, or prohibited phrases. For open-ended outputs, use a narrow semantic rubric and repeat important cases at the same model settings.
A high-risk route might require every security and schema test to pass, plus a 95 percent pass rate across repeated core-task fixtures. Track latency, token use, lowest score, error count, and refusal quality against the prior release.
PromptDoctor research describes a tool for detecting and correcting issues involving bias, vulnerability, and performance in developer prompts. Its PromptDoctor overview is useful context, but an auto-fix remains advisory and needs human review. It may remove a risky phrase while changing a product requirement, so it isn’t a substitute for security review.
Apply the same standards to AI content directories
Prompt linting matters for content products, not only agents and chatbots. If you publish a general AI tool directory, a complete AI tools list, or a comprehensive AI list, your prompts need source, category, and pricing rules.
A page about best AI tools 2026, new AI tools 2026, or top-rated AI software should prohibit invented ratings and unsupported pricing. It should also distinguish a free AI tools list from a premium AI software list.
Content and writing AI requests need tighter categories. An AI writing tools list may compare best AI copywriter tools, AI blog post generators, AI grammar checkers, and AI essay writing tools. Your prompt contract should require selection criteria, cited evidence, and clear disclosure when information is unavailable.
Key takeaways
- Treat prompts as versioned interfaces with explicit security, format, tool, and fallback requirements.
- Use prompt linting to block recognizable unsafe patterns before deployment.
- Keep static analysis separate from behavioral evals, schema validation, and runtime guardrails.
- Store fixtures with the context that changes model behavior, then test failures you have actually seen.
- Give critical findings hard release gates, while routing lower-risk warnings to review.
Frequently asked questions
Can prompt linting prevent every prompt injection attack?
No. It can flag configured patterns and enforce safer prompt structure. You still need least-privilege tools, input handling, output validation, runtime monitoring, and tests against adversarial fixtures.
What should fail a deployment immediately?
Block releases for exposed secrets, successful injection tests, schema violations on machine-consumed output, unsafe tool permissions, and confirmed sensitive-data leaks. Style issues and small token increases usually belong in warnings unless they violate a route-specific policy.
Should every prompt require JSON output?
No. Use a schema when software needs predictable fields or the response triggers an action. Free-form content can use an editorial contract that checks source-grounding, prohibited claims, and semantic quality.
Build safer releases with layered evidence
Prompt linting makes unsafe or incomplete instructions visible before they become production behavior. It exposes known structural and policy problems, but it can’t prove safe runtime behavior on its own.
Combine prompt linting with fixtures, behavioral evaluations, output validation, and monitored releases. Together, these layers make prompt optimization an evidence-based process, supported by lint findings, fixtures, output validation, and monitored releases. That layered evidence gives you a clearer basis for shipping prompt changes than a polished demo ever can.
Leave a Reply